How to scrape it. With code that runs.
Each guide answers one question, shows the request, and says what a page costs.
 · How to scrapeDo I need a web scraping API? Often not. Here is what we measured
Python requests and a browser you run yourself read most pages for free. Cases measured on our test store show when an API earns its price.
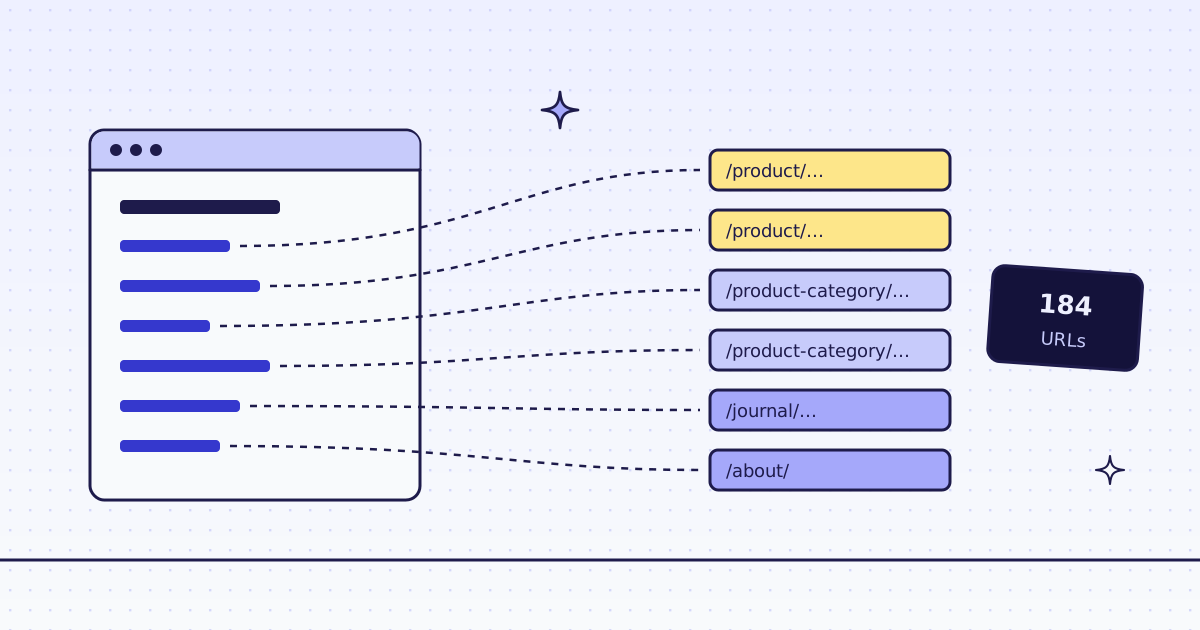 · How to scrapeHow to extract all links from a website
Get every link on one page with its anchor text, then every URL of the whole site from its sitemaps. Python code, real counts and costs on our test store.
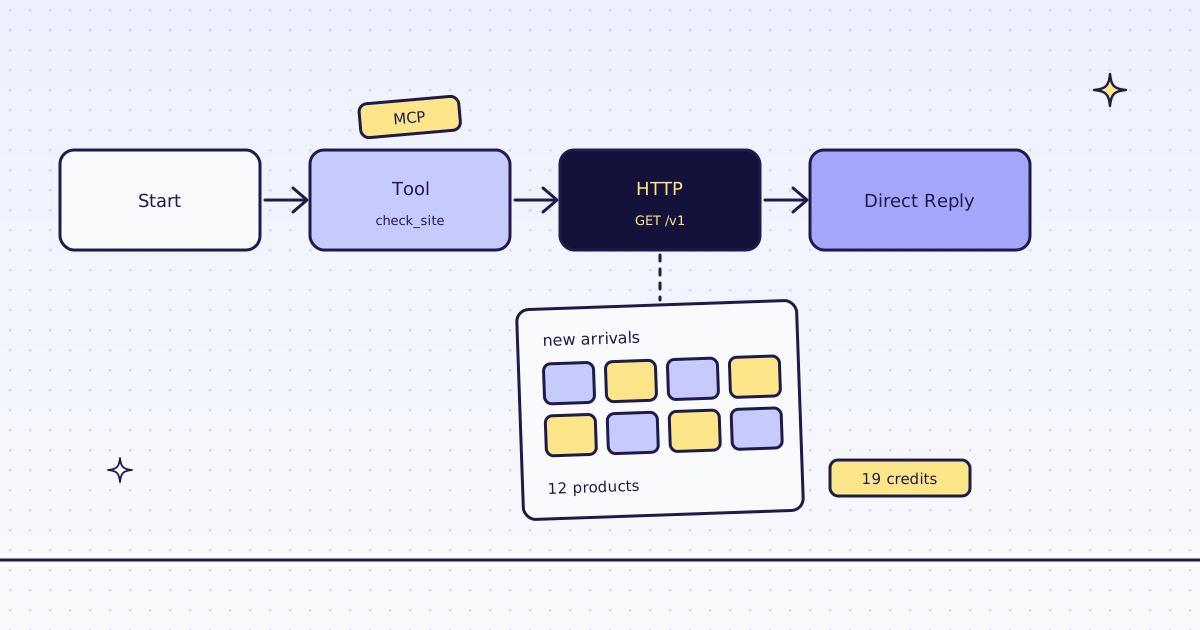 · AI agentsFlowise web scraping: read pages in an Agentflow, no browser to host
Read web pages in a Flowise Agentflow with our MCP server and the HTTP node. A JavaScript page gave 12 products for 19 credits. Tested in Flowise 3.1.4.
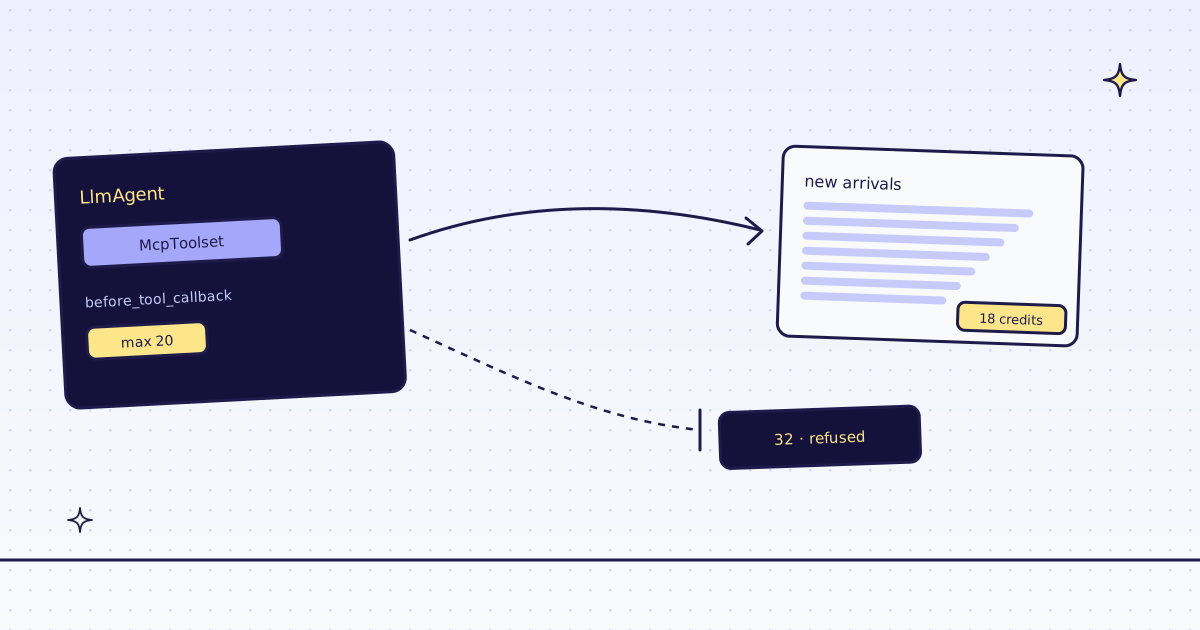 · AI agentsGoogle ADK web scraping: MCP tools with a cap the model cannot raise
Connect a Google ADK agent to our MCP server with McpToolset, keep three tools, and cap each page in a before_tool_callback. Tested on google-adk 2.14.
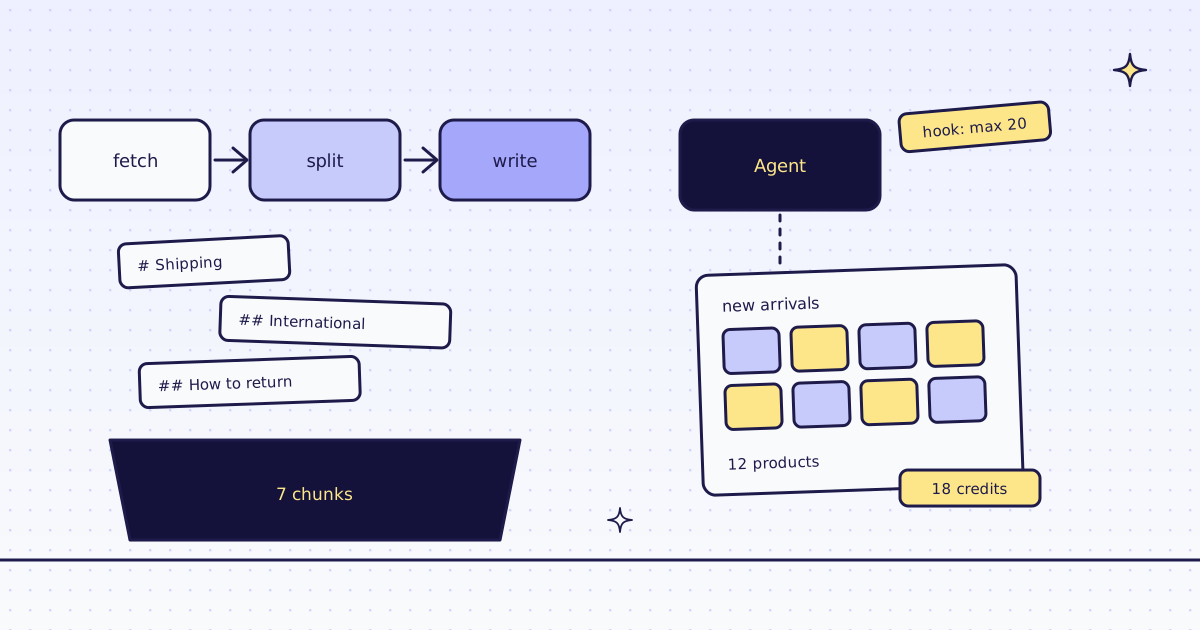 · AI agentsHaystack web scraping: pages as Markdown, MCP tools with a cap
Feed web pages into a Haystack pipeline as Markdown split at headings, and give a Haystack Agent MCP web tools with a cost cap. Tested on Haystack 3.5.
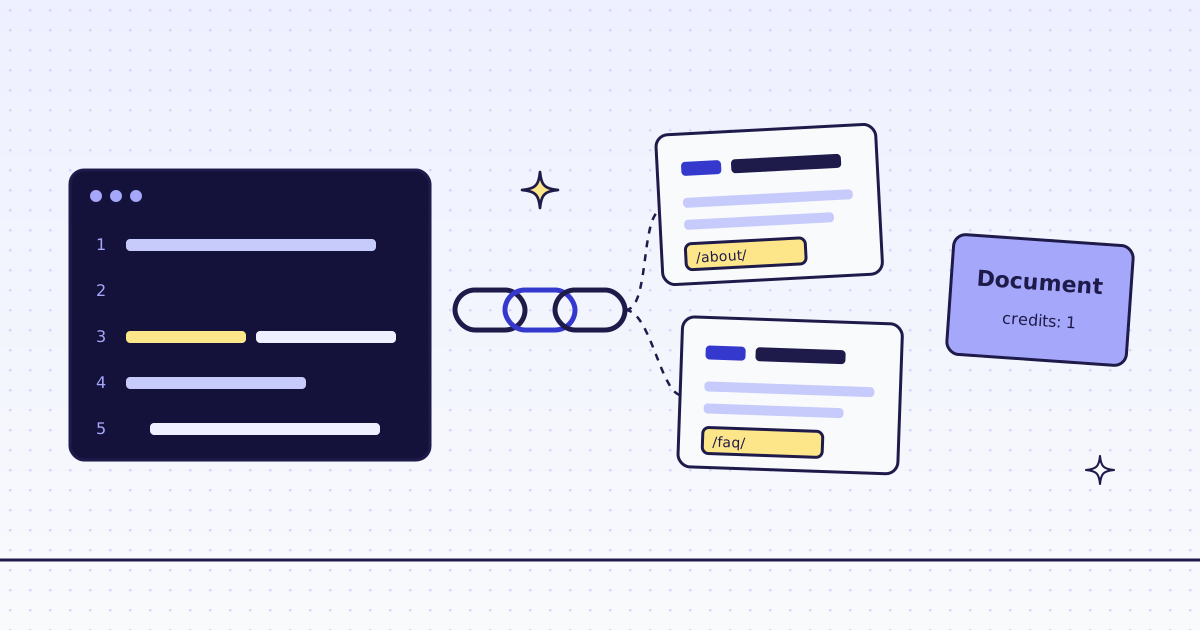 · AI agentsWeb scraping with LangChain: a page loader in 5 lines
Load web pages as Markdown LangChain documents in 5 lines, crawl a site, and give an agent tools with a credit cap. Measured on our test store.
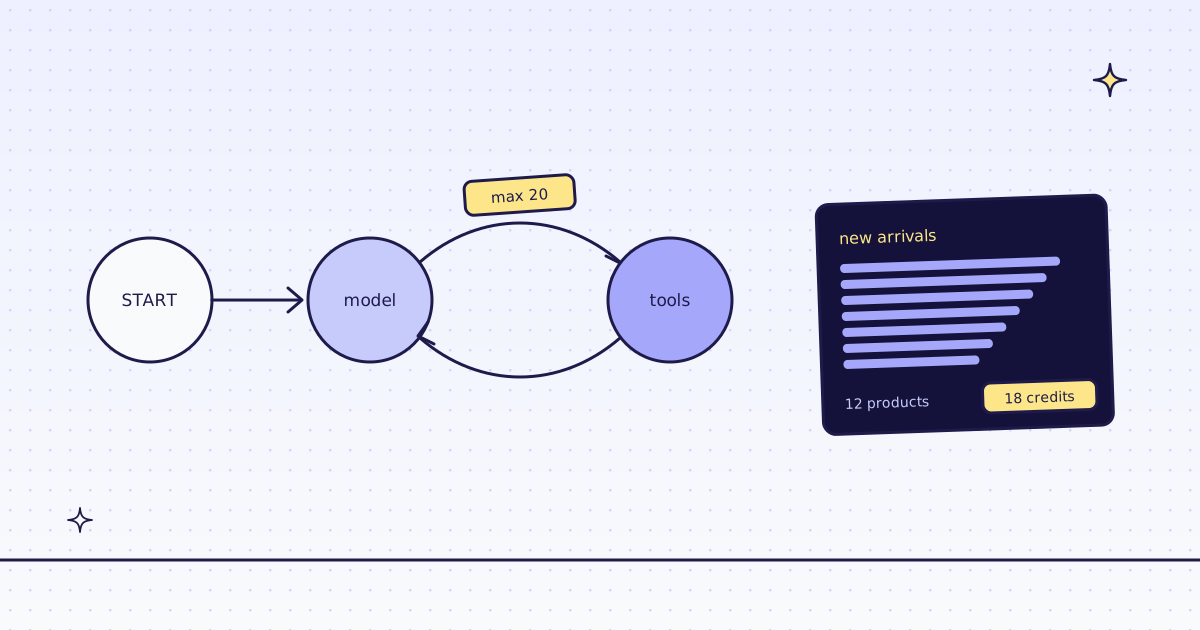 · AI agentsLangGraph web scraping: MCP tools in a graph, with a cost cap
Load our MCP tools into a LangGraph ToolNode with langchain-mcp-adapters, keep three, and cap each page in an interceptor. Tested on LangGraph 1.2.
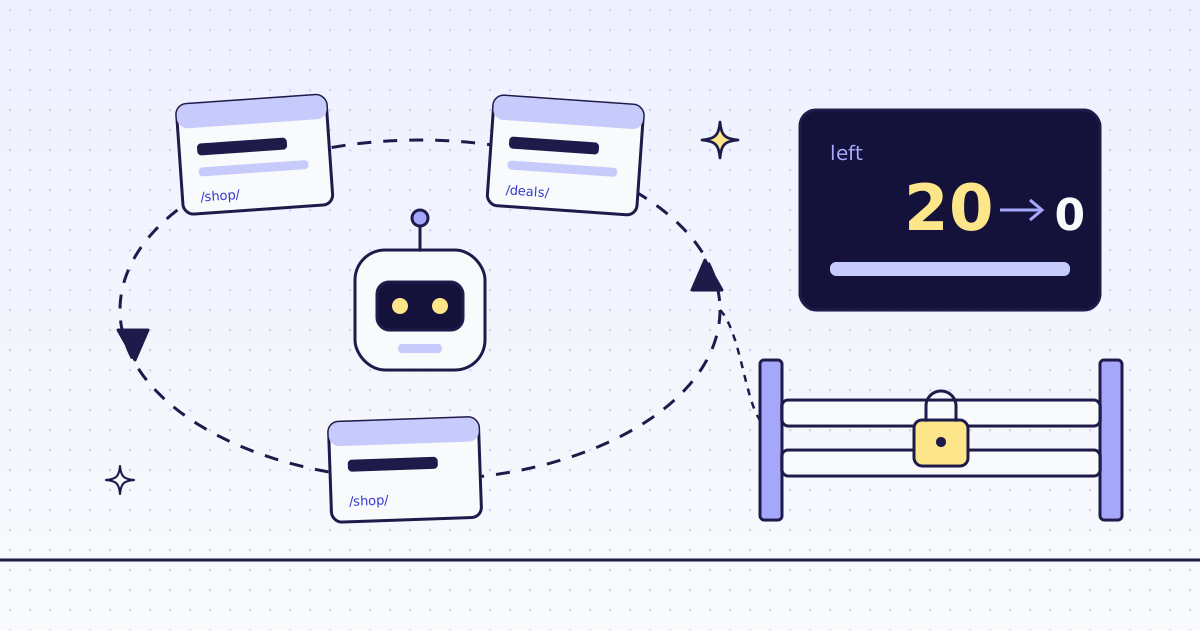 · AI agentsCap what an AI agent spends on web pages
Stop a looping AI agent from burning credits on web pages. A free price check, a cap per page, a budget per run and a monthly cap, measured on our Lab.
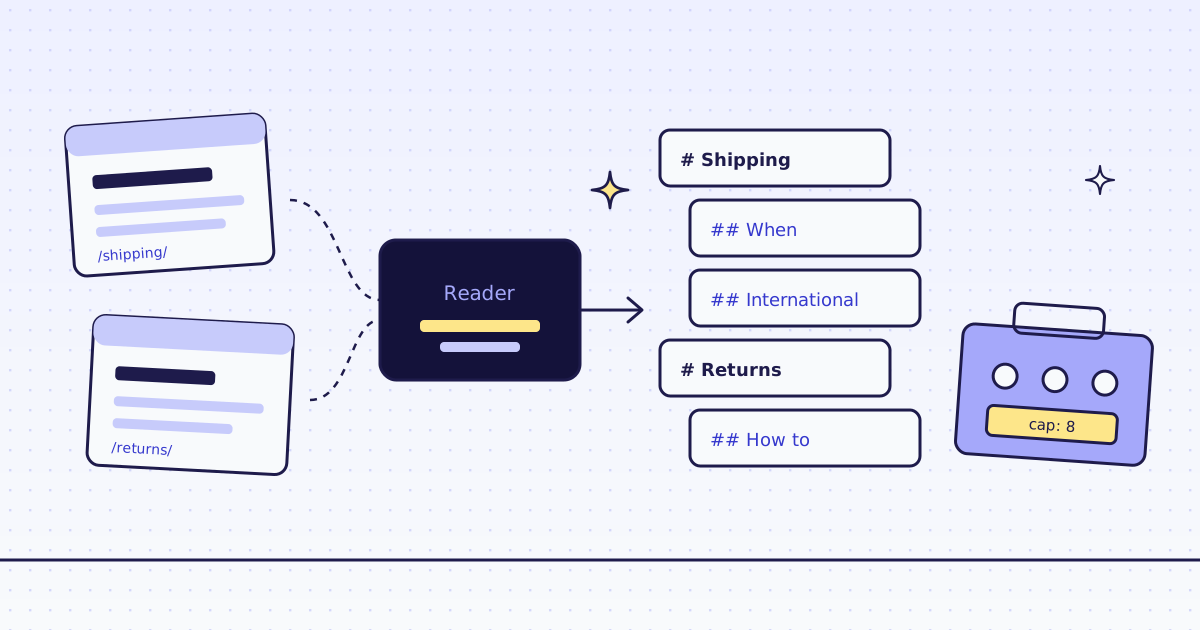 · AI agentsLlamaIndex web scraping: pages as documents, tools for agents
Load web pages into LlamaIndex as clean Markdown documents, split them at headings, and give an agent web tools with a credit cap. Measured on our Lab.
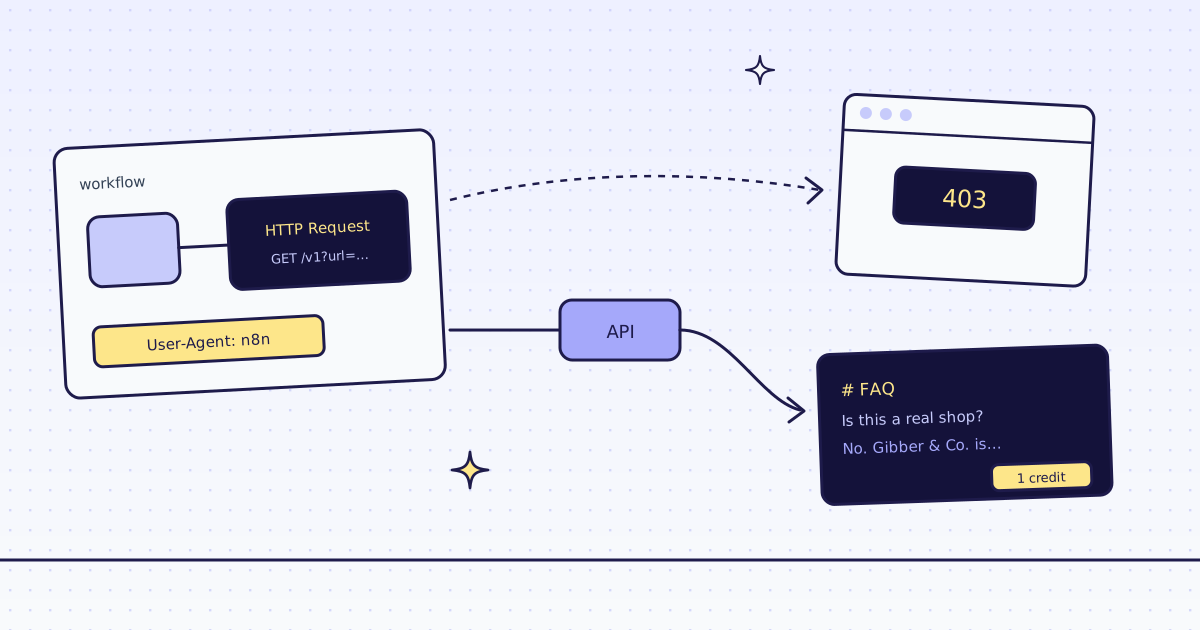 · How to scrapen8n HTTP Request node gets 403 Forbidden: why, and the fix
The n8n HTTP Request node tells every site it is n8n. What it sends, what a header can fix, and how one changed URL gets the page. Tested in n8n 2.47.
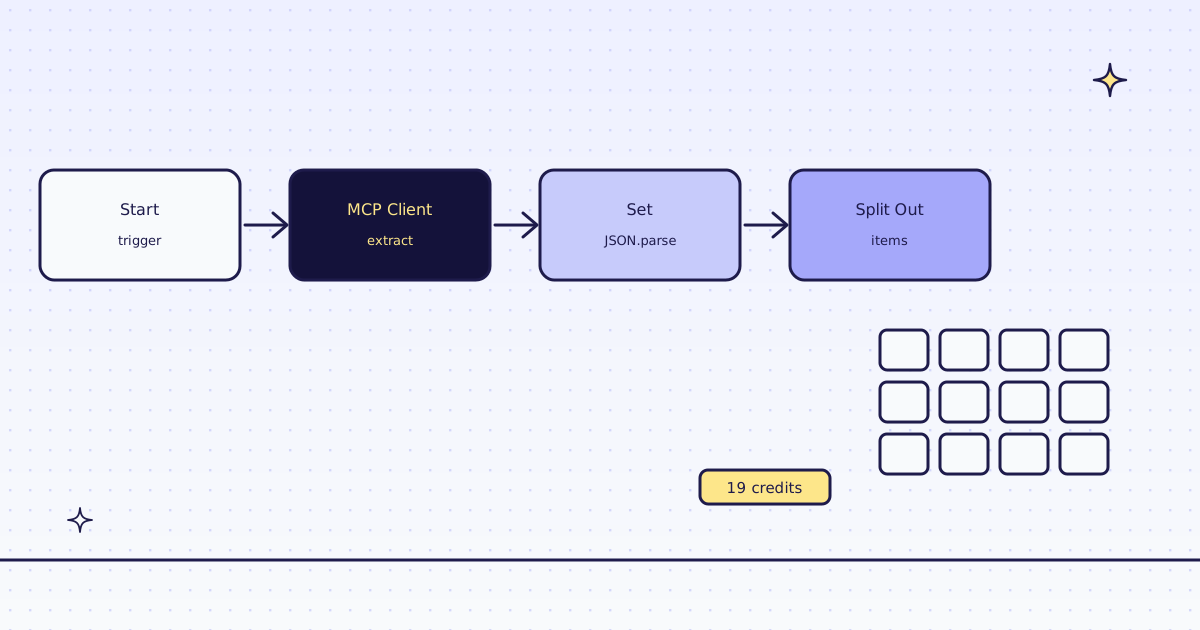 · How to scrapen8n MCP Client: scrape web pages from a workflow, no code
Point n8n's MCP Client node at our MCP server, call check_site, scrape or extract, and turn the rows into n8n items. Tested in n8n 2.47 on our test store.
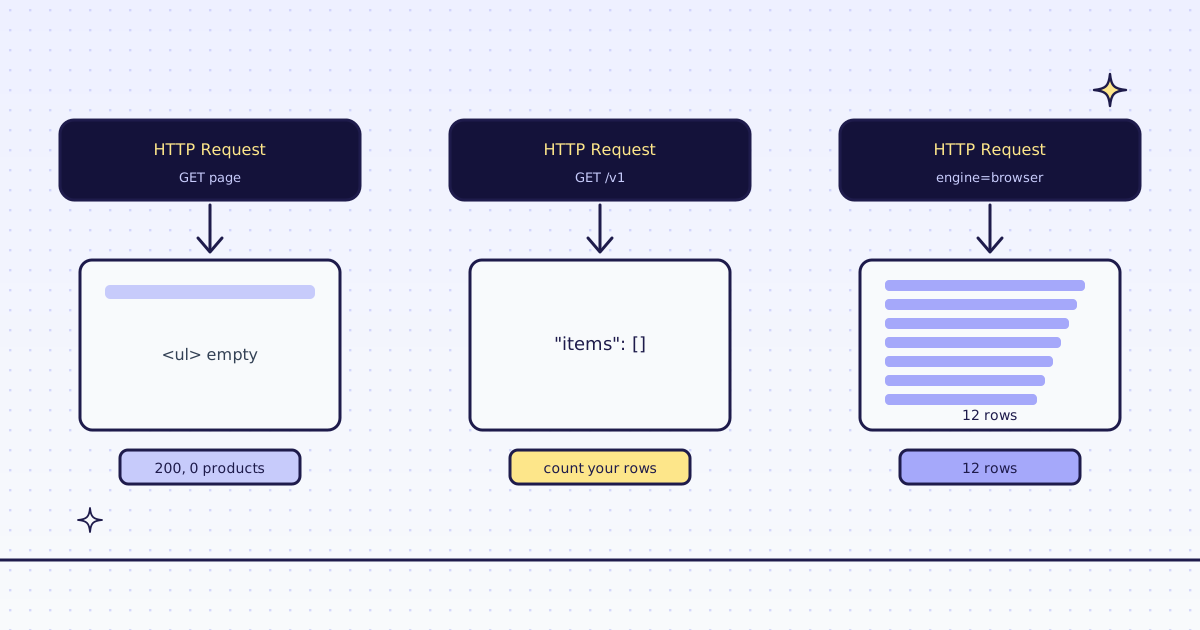 · How to scrapen8n: scrape a JavaScript website when HTTP Request gets nothing
The n8n HTTP Request node gets the page but not the list a browser draws. Two more query parameters get every item. Tested in n8n 2.47 on our test store.