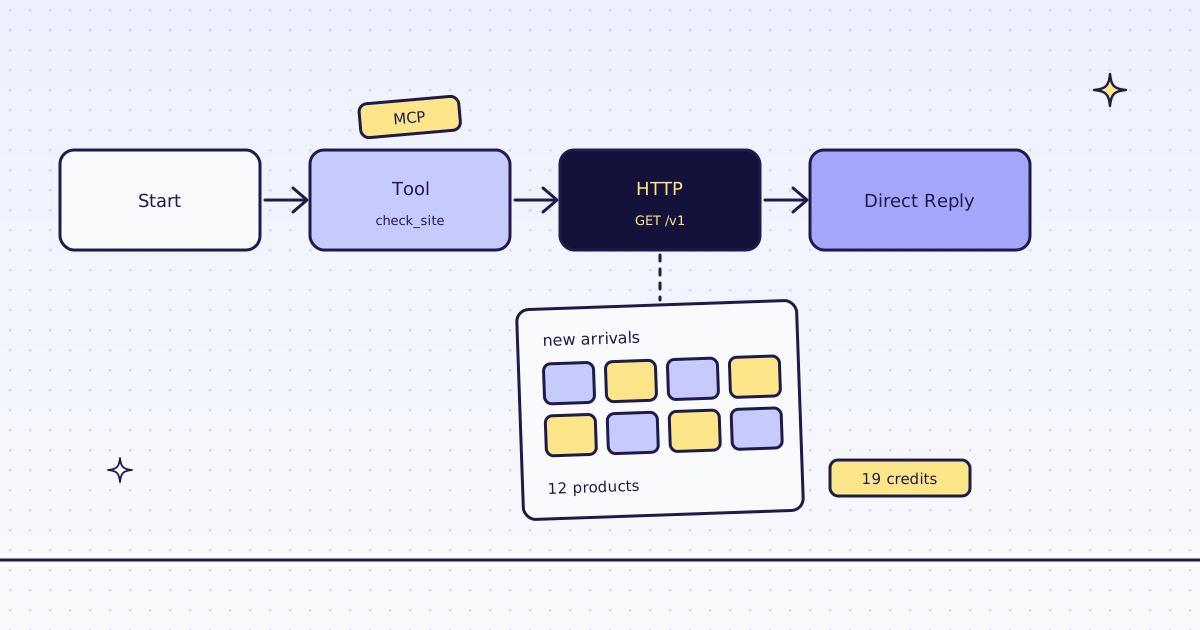
Where the HTTP Request node stops
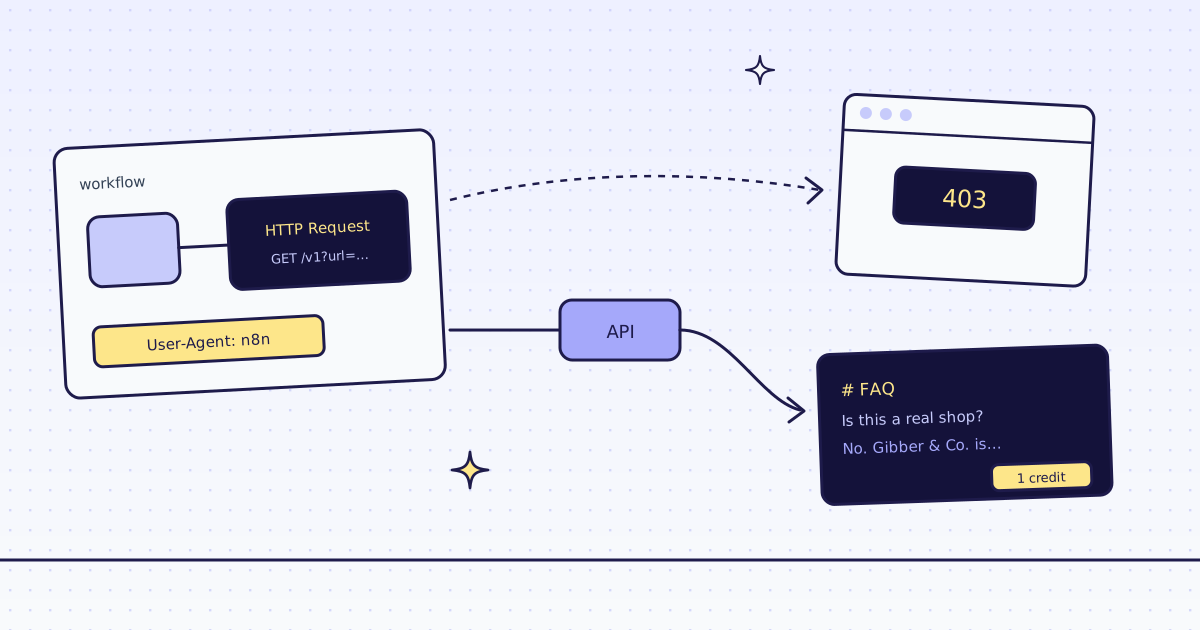
- A 403 or a bot check. The node tells every site it is n8n. These are the headers it sent to our echo server, measured in n8n 2.47.7:
What the site sees
User-Agent: n8n
Accept: application/json,text/html,application/xhtml+xml,application/xml,text/*;q=0.9, image/*;q=0.8, */*;q=0.7
Accept-Encoding: gzip, compress, deflate, br
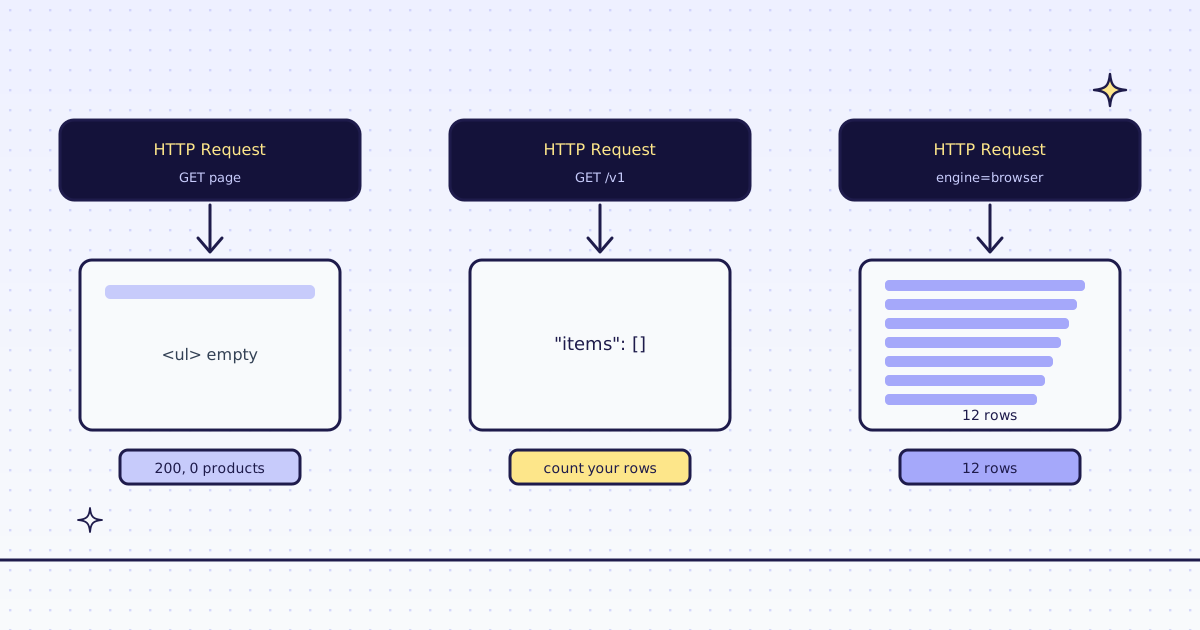
- A JavaScript page. The node downloads the HTML and never runs the page's script. On our test store's new arrivals page it got 56 KB of HTML and 0 products, with a 200.
- Too much HTML. Menus, scripts and footers, when your next node only wants the text or a few fields.
The fix: the same node, our API
No new node to install. Change the URL, add the page as a query parameter, and keep your key in an n8n credential, never in the URL:
HTTP Request node
URL:              https://get.megalania.io/v1
Authentication:   Header Auth  →  Authorization: Bearer meg_sk_...
Query parameters: url            = https://lab.megalania.io/new-arrivals/
                  response_types = json
                  extract        = items:#arrivals li{name:h2|price:.price}*
                  engine         = browser
                  actions        = wait_for:#item-12
What it returned on our dev cluster on 16 Nov 2026, for the page the plain node saw as empty:
Output
statusCode: 200
x-route: browser/datacenter
x-credits-charged: 19
data.items: 12 rows
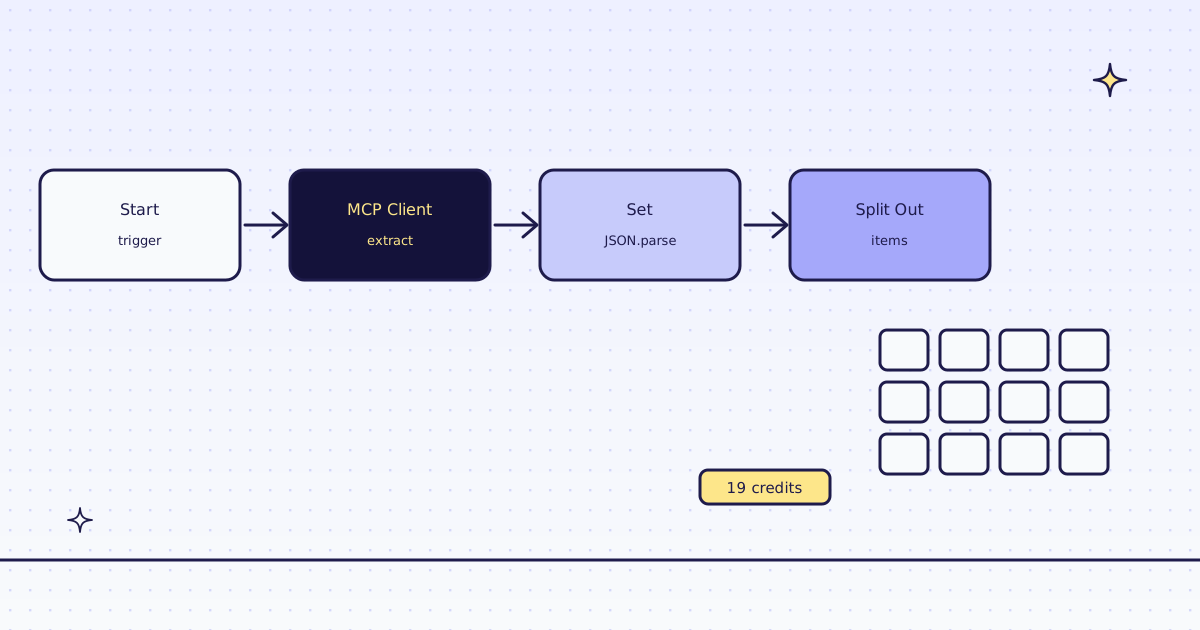
12 products, from a real Chrome on our side, for 19 credits: 15 for the browser, 1 for the JSON, 3 for the wait. A plain page over HTTP costs 1 credit. A block we detect costs nothing. The step by step is in n8n: scrape a JavaScript website, and the 403 case in n8n HTTP Request node gets 403 Forbidden.
Three ways in
- The HTTP Request node, as above. Works on any n8n, including n8n Cloud.
- The MCP Client node (n8n 2.47): pick a tool by name, no URL fields.
check_sitetells you a site's price for free:
MCP Client node
MCP Endpoint URL: https://mcp.megalania.io/
Authentication:   Bearer Auth  →  meg_sk_...
Tool:             check_site   →  {"host": "lab.megalania.io"}
→ {"browser": 15, "browser_residential": 32, "datacenter": 1, "residential": 8} free- Our community node,
n8n-nodes-megalania, for self-hosted n8n: a form with Scrape, Map site and Batch. See Web scraping in n8n without running a browser and the n8n guide. - Flowise: the same two ways, the HTTP node and Custom MCP, in an Agentflow. See Flowise web scraping.
- Make and Zapier: the HTTP Request call is one GET with query parameters and one header, so their HTTP modules can send it too. We tested in n8n only.
Tips that save credits
- Try the free way first. If the plain node gets your data, you do not need us for that page.
- Count your rows. An empty list can come back as a 200, from n8n alone and from us. Our check for JavaScript shells misses some pages. An IF node on the item count catches it.
- Use the browser only where needed. It costs more. Send
engine=browseronly for pages that come back empty. - Turn on Never Error to branch on our errors instead of stopping. On an error, n8n puts our JSON in
body, notdata.
Limits
- Public pages only. We do not log in, and we do not solve CAPTCHAs. When a page needs either, we stop and say so, for free.
- Rules break when a site changes its layout. You get empty fields, not an error.
- Browser pages cost more. Plans and prices are on the pricing page.
Free beta, by invite76,000 credits for 30 days, no card. Apply, and we email your invite.Apply for the beta