What you get
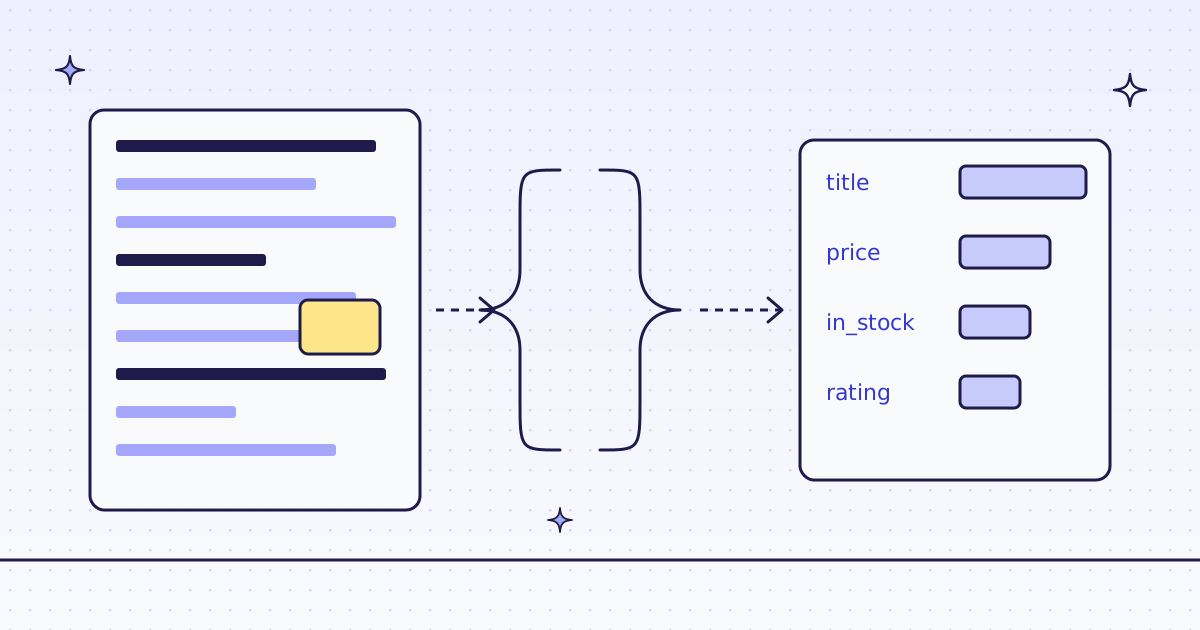
- One row per article. Title, link, date, category and tags from one
extractrule on the list page, plus the link to the next page. - Only new posts. The script remembers the links it has seen and stops paging at the first page that has one.
- A fresh copy every time.
max_age=0skips our recent copy, so a post published a minute ago is not missed.
A feed in one script
This uses our Python SDK. It reads the journal of our test store, the Lab, page by page, and appends new posts to posts.jsonl.
Shell
pip install megalania
export MEG_API_KEY='meg_sk_...'
news.py
import json
import os
import pathlib

from megalania import Megalania

RULES = "posts:article{title:.entry-title|link:.posted-on a@href|date:time@datetime|category:.cat-links a|tags:.tags-links}*|next:a.next@href"
SEEN = pathlib.Path("seen.json")

seen = set(json.loads(SEEN.read_text())) if SEEN.exists() else set()
new, pages, spent = [], 0, 0
url = "https://lab.megalania.io/journal/"
with Megalania(os.environ["MEG_API_KEY"]) as meg:
    while url:
        r = meg.scrape(url, response_types="json", extract=RULES, max_age=0)
        page = json.loads(r.text)
        pages += 1
        spent += r.headers.credits_charged or 0
        fresh = [p for p in page["posts"] if p["link"] not in seen]
        new += fresh
        url = page["next"] if len(fresh) == len(page["posts"]) else None

for p in new:
    p["tags"] = p["tags"].removeprefix("Tags: ").split(", ")
with open("posts.jsonl", "a") as f:
    f.writelines(json.dumps(p, ensure_ascii=False) + "\n" for p in new)
SEEN.write_text(json.dumps(sorted(seen | {p["link"] for p in new})))
print(pages, "pages,", spent, "credits,", len(new), "new posts")
for p in new[:2]:
    print(p["date"][:10], p["category"], "|", p["title"], p["tags"])
What it printed on our dev cluster on 17 Nov 2026, run twice:
Output
3 pages, 6 credits, 14 new posts
2026-10-30 Guides | Map and compass: the five-minute basics ['hiking', 'navigation', 'safety']
2026-10-14 Care & Repair | Why you must dry your tent after every trip ['camping', 'care', 'tents']

(the same script again)
1 pages, 2 credits, 0 new posts
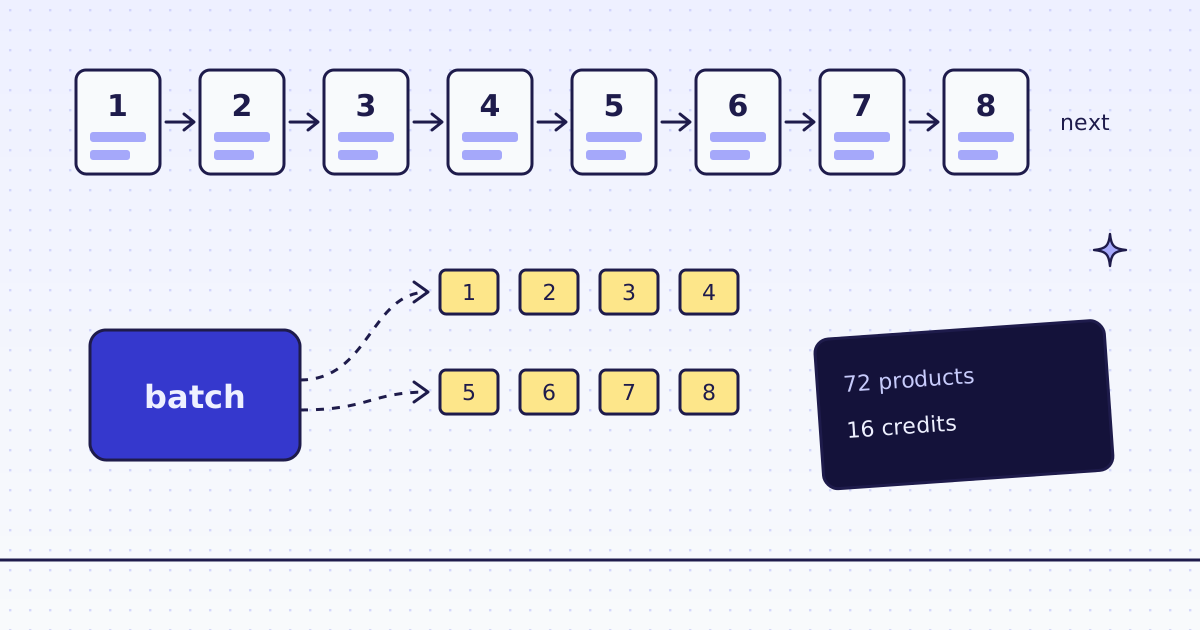
The first run read the 3 list pages and found 14 posts, for 6 credits: 2 a page. The second run read page 1, saw only known posts and stopped, for 2 credits. One line of posts.jsonl:
posts.jsonl
{"title": "Map and compass: the five-minute basics", "link": "https://lab.megalania.io/reading-a-map-and-compass/", "date": "2026-10-30T08:15:00+00:00", "category": "Guides", "tags": ["hiking", "navigation", "safety"]}- Try the feed first. The Lab has an RSS feed at
/feed/, free, but it lists only the newest 10 of the 14 posts. It is enough to catch new posts, not to fill the history. - Tags come as one string. The page prints
Tags: hiking, navigation, safety; the script cuts the label and splits the list. - The article itself is one more call: send its link with
response_types=markdownto get the main text without the menu and footer.
Run it on a schedule
- A cron job is enough. Each run costs 2 credits when nothing is new.
- Or let us watch. A monitor checks the list page on a schedule and sends a signed webhook when it changes. See Monitors.
Limits
- Public pages only. We do not log in, and we do not solve CAPTCHAs. Paywalled articles stay paywalled.
- Read the site's terms. Titles and links are fine to track; republishing full articles usually is not.
- Page text is untrusted. An article can carry instructions for a model. Keep it in the data part of your prompt.
- Prices of plans are on the pricing page.
Free beta, by invite76,000 credits for 30 days, no card. Apply, and we email your invite.Apply for the beta