How to scrape it. With code that runs.
Each guide answers one question, shows the request, and says what a page costs.
 · AI agentsCrawl a docs site into Markdown for RAG
Turn a documentation site into clean Markdown files for RAG. Check llms.txt, read the sitemap, fetch each page as Markdown, and keep code blocks intact.
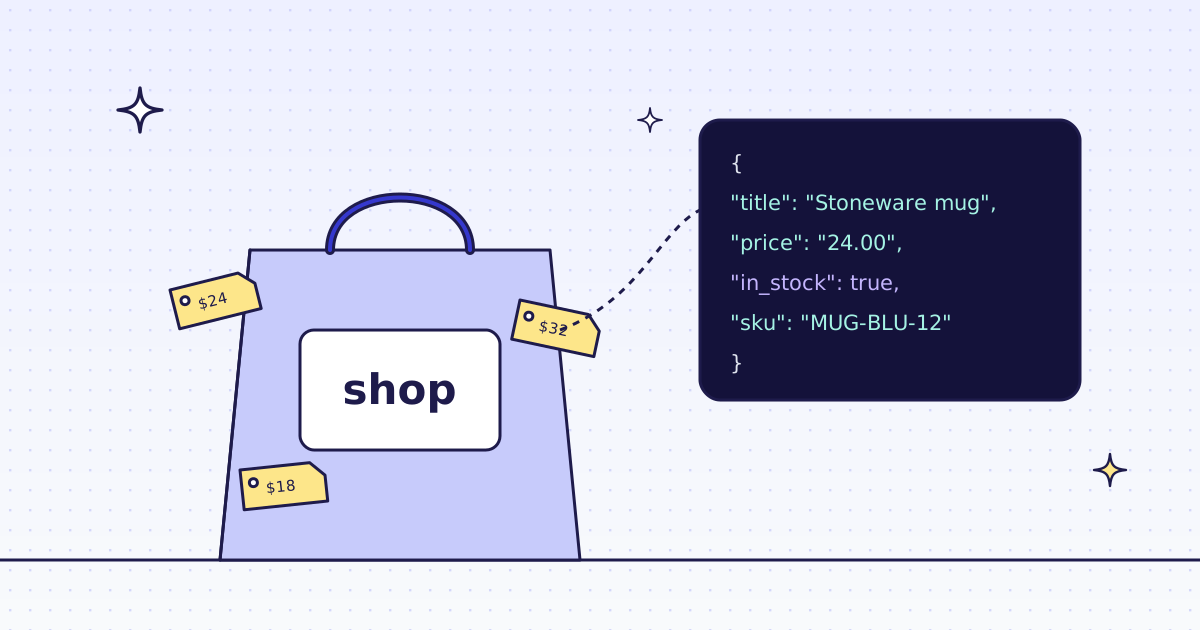 · How to scrapeHow to scrape any Shopify store
Get title, price, currency, stock and SKU from any Shopify product page as JSON. The free products.json route first, then one request in cURL or Python.
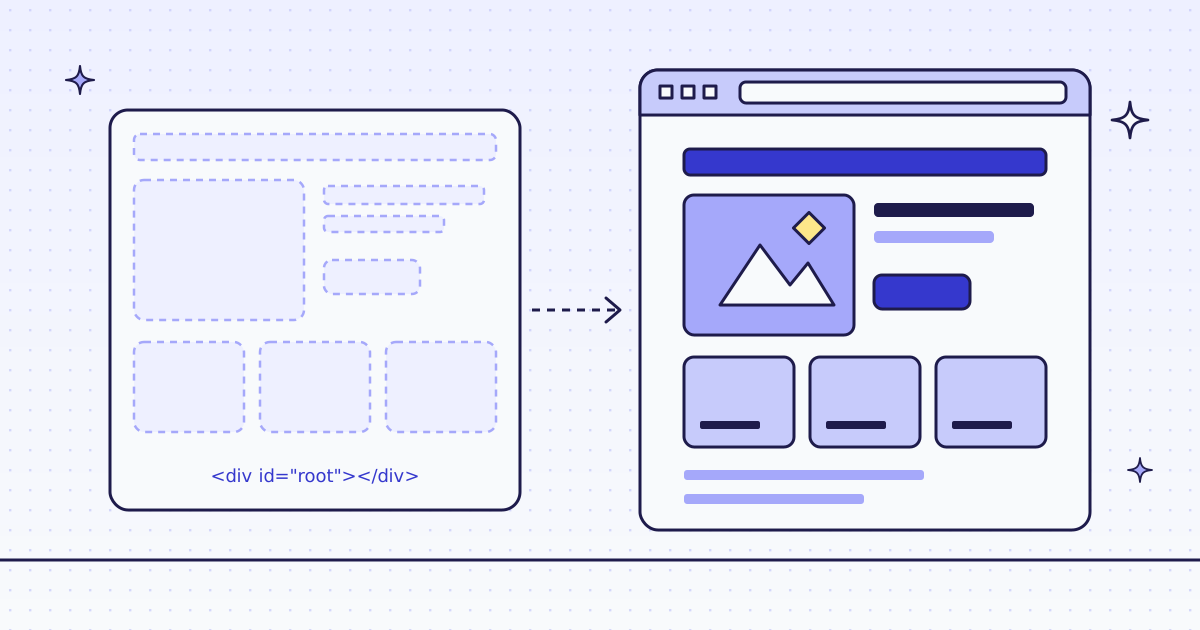 · How to scrapeHow to scrape JavaScript-rendered pages
First check if you need a browser at all. A three-request test, then one render with engine browser when you must. Real page sizes and costs inside.
 · How to scrapeHow to scrape job postings from company career pages
Most career pages carry a JobPosting JSON-LD block. Read title, location, type, date and company in one plain HTTP request, no browser. Real costs inside.
 · AI agentsGive your AI agent web access with an MCP server
Add one MCP server and your agent can check a site for free, then fetch any public page as clean Markdown. One setup command, real page sizes and costs.
 · How to scrapeHow to scrape product data from any store
Most stores publish name, SKU, price and stock as JSON-LD for search engines. Read it on any platform with one request and no selectors, in cURL or Python.
 · How to scrapeHow to track competitor prices and stock every day
A daily price and stock tracker in one Python file. Fetch each product page as JSON, save a snapshot, diff it with yesterday's. Real page costs inside.
 · AI agentsTurn any web page into Markdown for an LLM
Send one request with response_types markdown and get the page's main content back as clean Markdown, menus and footers gone. Real token counts inside.
 · How to scrapeHow to scrape any WooCommerce store
Get name, price, stock and SKU from WooCommerce product pages. Try the free Store API first, then one request in cURL or Python, with real page costs.