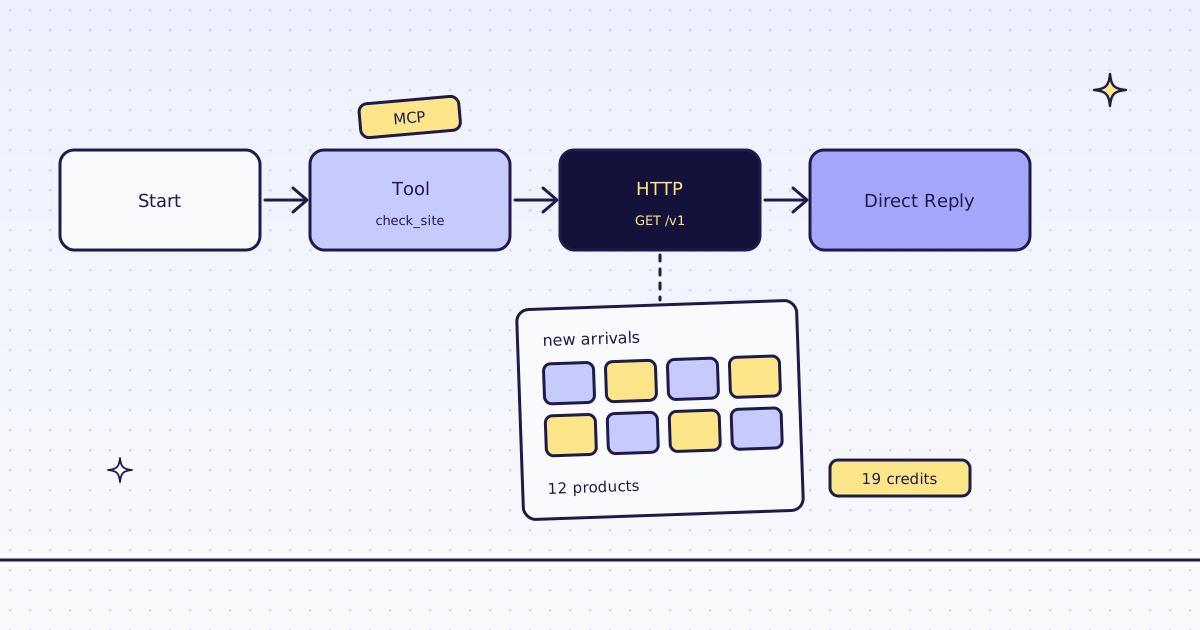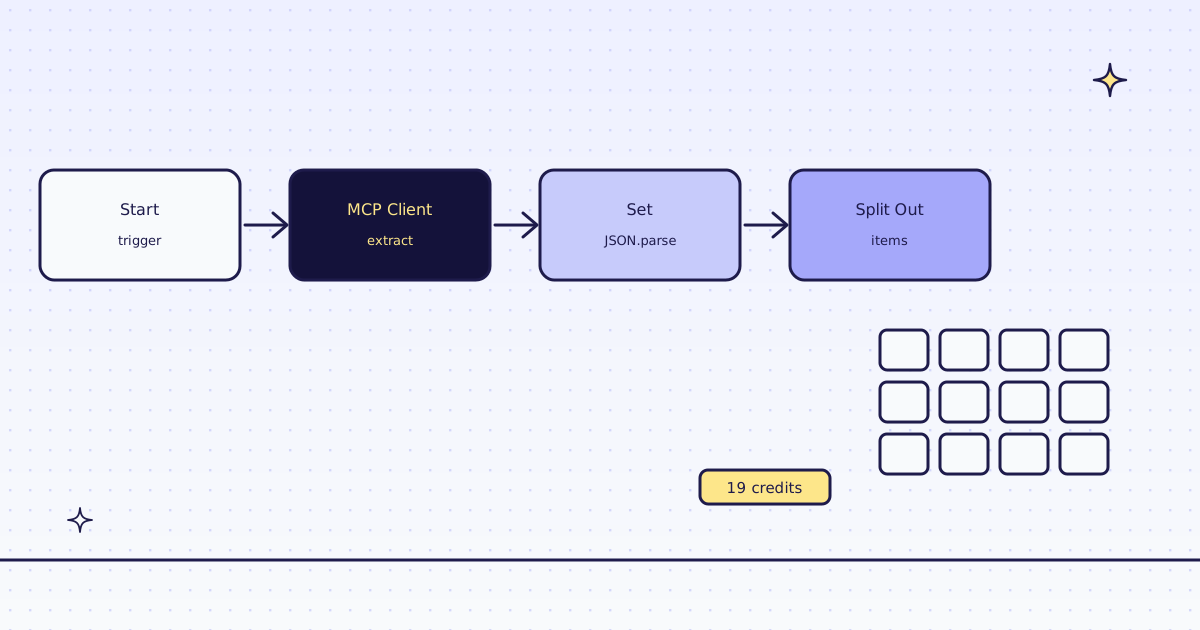
The short answer: n8n 2.47 has an MCP Client node that calls one tool of any MCP server, with no AI Agent and no code. Point it at our server, https://mcp.megalania.io/, with Bearer Auth and your key. Pick a tool: check_site for a host’s price (free), scrape for a page as Markdown, or extract for fields as JSON. On our test store’s new arrivals page, a page drawn by JavaScript, extract in the browser returned all 12 products for 19 credits, and two more nodes turned them into 12 n8n items.
Why the MCP Client node
You can call our API from an HTTP Request node too (see Web scraping in n8n without running a browser). The MCP Client node is simpler in one way: it reads the server’s tool list, so n8n shows each tool by name, and the same server and key work later for n8n’s AI Agent through the MCP Client Tool node.
Set up the node
| Setting | Value |
|---|---|
| MCP Endpoint URL | https://mcp.megalania.io/ |
| Authentication | Bearer Auth, with a new credential: Token meg_sk_... |
| Tool | check_site, scrape or extract (n8n lists all 15) |
| Input Mode | JSON |
The key lives in n8n’s credentials, sent as Authorization: Bearer ..., never in the URL. Get a key on the dashboard’s Keys page.
First: what does the site cost?
Tool check_site, JSON input:
{"host": "lab.megalania.io"}The node’s output, structuredContent.price.quotes:
{"browser": 15, "browser_residential": 32, "datacenter": 1, "residential": 8}Free. A page on this site costs 1 credit over plain HTTP and 15 in the browser. The output also shows our recent results on the host. Use it to decide, in an IF node, whether a page is worth the browser.
A page as Markdown
Tool scrape. The new arrivals page draws its list with JavaScript, so ask for the browser and wait for the 12th card:
{"url": "https://lab.megalania.io/new-arrivals/", "engine": "browser", "actions": [{"wait_for": "#item-12"}], "max_credits": 20}ok: true route: browser/datacenter credits_charged: 18 (15 route, 3 actions) chars: 2,670 of Markdown, 12 products with name, price and link next_step: "This page is a list: run inspect, then extract for clean rows."
max_credits: 20is the most this page may cost. If no route fits, the call is refused before any fetch, for free. In n8n you set it, not a model.- Without
engine: "browser"this page comes back as only its note: the list is drawn after the page loads. Our check for such pages did not flag this one, so count your rows.
Fields as n8n items
Tool extract returns fields by CSS rules instead of Markdown:
{"url": "https://lab.megalania.io/new-arrivals/", "engine": "browser", "actions": [{"wait_for": "#item-12"}], "extract": "items:#arrivals li{name:h2|price:.price}*", "max_credits": 20}The rows come back as a JSON string in structuredContent.content, so n8n needs one step to read them:
- Edit Fields (Set) node: add a field
items, type Array, value{{ JSON.parse($json.structuredContent.content).items }}. - Split Out node: field
items.
12 items
first: {"name": "20 cm Chef’s Knife", "price": "$112.00"}
19 credits: 15 for the browser, 3 for the page action, 1 for the JSON. The ’ is the page’s own: the store’s script puts the name in as text, and a browser shows it too. A Set node with {{ $json.name.replace('’', '’') }} cleans it.
For n8n’s AI Agent
The MCP Client Tool node connects the same server to an AI Agent node, as tools the model can call. Set the same URL and Bearer credential, and under Tools to Include pick only check_site, scrape and extract. We did not run an agent for this post: it needs your own model key. Over MCP the model fills max_credits, so set a monthly spend cap on your account for a hard limit.
What it costs
| Step | Credits |
|---|---|
check_site |
0 |
scrape in the browser, with one action |
18 |
extract in the browser, with one action |
19 |
A plain page (scrape, plain HTTP) |
1 |
A call refused by max_credits, a block we detect, or one of our errors |
0 |
These prices are for our test store on the datacenter route. A site that blocks it costs more, and check_site shows how much. All the rules are in Credits. Plans are on the pricing page.
How we measured: n8n 2.47.7 in Docker on 16 Nov 2026, the MCP Client node (version 1.1) with a Bearer Auth credential, against our dev cluster’s MCP server and the Lab store on our dev domain. Two workflows: check_site and scrape; then extract, Edit Fields and Split Out. The outputs above are copied from those runs.
Limits
- Page text is untrusted. If you pass pages to an AI Agent, a page can hide instructions for the model. Keep your own instructions separate from page text.
- Public pages only. We do not log in, and we do not solve CAPTCHAs. When a page needs either, we stop and say so, for free.
- Rules break when the site changes its layout. You get empty or
nullfields, not an error. Count your rows.
Every tool and argument is in MCP for agents. More on agents and MCP in Give your AI agent web access with an MCP server. Fetch public pages only. Read the site’s terms and robots.txt, and follow them.