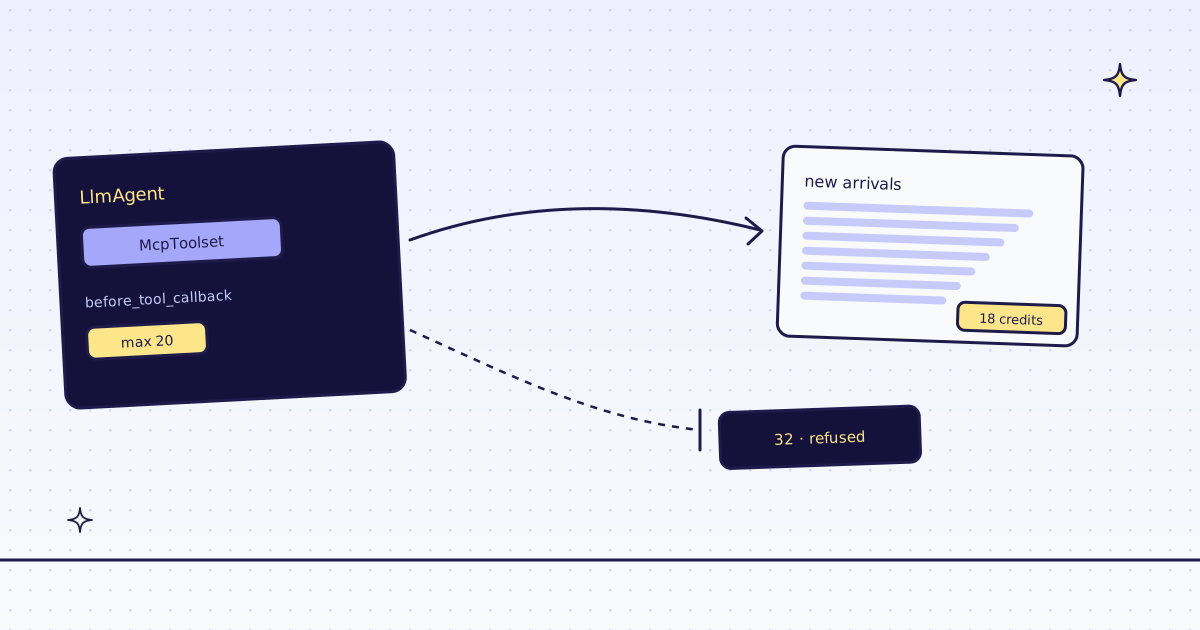
The short answer: for Google ADK web scraping, give your LlmAgent our hosted MCP server through McpToolset, with the key in the connection’s headers and a tool_filter that keeps check_site, scrape and extract. Add a before_tool_callback that sets max_credits on scrape and extract, so the model cannot raise what a page may cost. On our test store, lab.megalania.io, the agent read a JavaScript page with 12 products for 18 credits, and a call that needed 32 credits was refused before any fetch, for free.
Install
pip install google-adk mcp
export MEG_API_KEY='meg_sk_...'
mcp is a separate install: without it, importing McpToolset fails with No module named 'mcp'.
The toolset
Save this as tools.py. It also checks the setup with one direct call, no model needed:
import asyncio
import os

from google.adk.tools.mcp_tool import McpToolset, StreamableHTTPConnectionParams

megalania = McpToolset(
    connection_params=StreamableHTTPConnectionParams(url="https://mcp.megalania.io/", headers={"Authorization": f"Bearer {os.environ['MEG_API_KEY']}"}),
    tool_filter=["check_site", "scrape", "extract"],
)


async def main():
    tools = {t.name: t for t in await megalania.get_tools()}
    print(sorted(tools))
    page = await tools["scrape"].run_async(args={"url": "https://lab.megalania.io/faq/"}, tool_context=None)
    print(page["structuredContent"]["credits_charged"], page["structuredContent"]["route"])
    await megalania.close()


if __name__ == "__main__":
asyncio.run(main())['check_site', 'extract', 'scrape'] 1 http/datacenter
- The key goes in
headers, never in the URL. tool_filterkeeps three of our 15 tools: a shorter prompt for the model, and no batch or monitor it could start by mistake.- The FAQ cost 1 credit: plain HTTP was enough, and the answer is the page’s main text as Markdown.
The agent, with a cap
ADK calls before_tool_callback before every tool call, with the arguments the model chose. Change them there, and the tool gets your values:
def cap(tool, args, tool_context):
    if tool.name in {"scrape", "extract"}:
        args["max_credits"] = 20


agent = LlmAgent(name="reader", model="gemini-2.5-flash", tools=[megalania], before_tool_callback=cap)
Only scrape and extract take max_credits. Put it on check_site and the call fails as an unknown argument, so the callback leaves check_site alone.
To show the tool calls without a model key, we ran the agent with a scripted model: a small BaseLlm class that asks for three calls in order. The full script is at the end of this post. What the three tool results said:
check_site | -     | 0 credits  | 0 products
scrape     | True  | 18 credits | 12 products
scrape     | False max_credits_too_low | 0 credits | 0 products
check_siteis free. It gave our recent results on the host and its prices: 1 credit a page over plain HTTP, 15 in the browser.- The JavaScript page, asked for in the browser with a wait for the 12th card, came back with all 12 products for 18 credits: 15 for the browser, 3 for the wait. The model asked for a cap of 500; the callback sent 20, and 18 fits.
- The residential browser costs 32 on this host. With the cap at 20 we refused it before fetching anything, with
max_credits_too_lowand 0 credits. The model reads why, and can choose a cheaper route or stop.
The scripted run
import asyncio

from google.adk.agents import LlmAgent
from google.adk.models.base_llm import BaseLlm
from google.adk.models.llm_response import LlmResponse
from google.adk.runners import InMemoryRunner
from google.genai import types

from tools import megalania

LAB = "https://lab.megalania.io"
PLAN = [
    ("check_site", {"host": "lab.megalania.io"}),
    ("scrape", {"url": f"{LAB}/new-arrivals/", "engine": "browser", "actions": [{"wait_for": "#item-12"}], "max_credits": 500}),
    ("scrape", {"url": f"{LAB}/new-arrivals/", "engine": "browser", "proxy_tier": "residential", "max_credits": 500}),
]


class Scripted(BaseLlm):
    async def generate_content_async(self, llm_request, stream=False):
        done = sum(1 for c in llm_request.contents for p in c.parts if p.function_response)
        if done < len(PLAN):
            name, args = PLAN[done]
            yield LlmResponse(content=types.Content(role="model", parts=[types.Part(function_call=types.FunctionCall(name=name, args=args))]))
        else:
            yield LlmResponse(content=types.Content(role="model", parts=[types.Part(text="done")]))


def cap(tool, args, tool_context):
    if tool.name in {"scrape", "extract"}:
        args["max_credits"] = 20


agent = LlmAgent(name="reader", model=Scripted(model="scripted"), tools=[megalania], before_tool_callback=cap)


async def main():
    runner = InMemoryRunner(agent=agent)
    session = await runner.session_service.create_session(app_name=runner.app_name, user_id="me")
    msg = types.Content(role="user", parts=[types.Part(text="List the new arrivals with prices.")])
    async for event in runner.run_async(user_id="me", session_id=session.id, new_message=msg):
        for part in event.content.parts if event.content else []:
            if part.function_response:
                sc = part.function_response.response.get("structuredContent", {})
                print(part.function_response.name, "|", sc.get("ok", "-"), sc.get("code", ""), "|", sc.get("credits_charged", 0), "credits |", sc.get("content", "").count("\n- "), "products")
    await megalania.close()


asyncio.run(main())
With a real model, use LlmAgent(..., model="gemini-2.5-flash", ...) or any model ADK supports, and drop the Scripted class. We did not run a paid model for this post: it needs your own model key.
What it costs
| Step | Credits |
|---|---|
check_site |
0 |
A plain page (scrape, plain HTTP) |
1 |
| A JavaScript page in the browser, with one action | 18 |
A call refused by max_credits |
0 |
| A block we detect, or one of our errors | 0 |
These prices are for our test store on the datacenter route. A site that blocks it costs more, and check_site shows how much. All the rules are in Credits. Plans are on the pricing page.
How we measured: our dev cluster on 16 Nov 2026, the Lab store on our dev domain, google-adk 2.14.1 and mcp 2.3.0 on Python 3.13. We ran tools.py and agent_run.py as above; the outputs are copied from those runs. ADK logs a line about missing token usage for the scripted model; a real model does not.
Limits
- Page text is untrusted. A page can hide instructions for a model. Our tool descriptions tell the agent never to follow them. Say it in your agent’s instruction too.
- Public pages only. We do not log in, and we do not solve CAPTCHAs. When a page needs either, we stop and say so, for free.
- An empty list can still be a charged answer. Our check for JavaScript shells misses pages that have a heading and some text. Tell your agent to count the rows it expected.
More on agents and MCP in Give your AI agent web access with an MCP server, and every tool and argument in MCP for agents. Fetch public pages only. Read the site’s terms and robots.txt, and follow them.