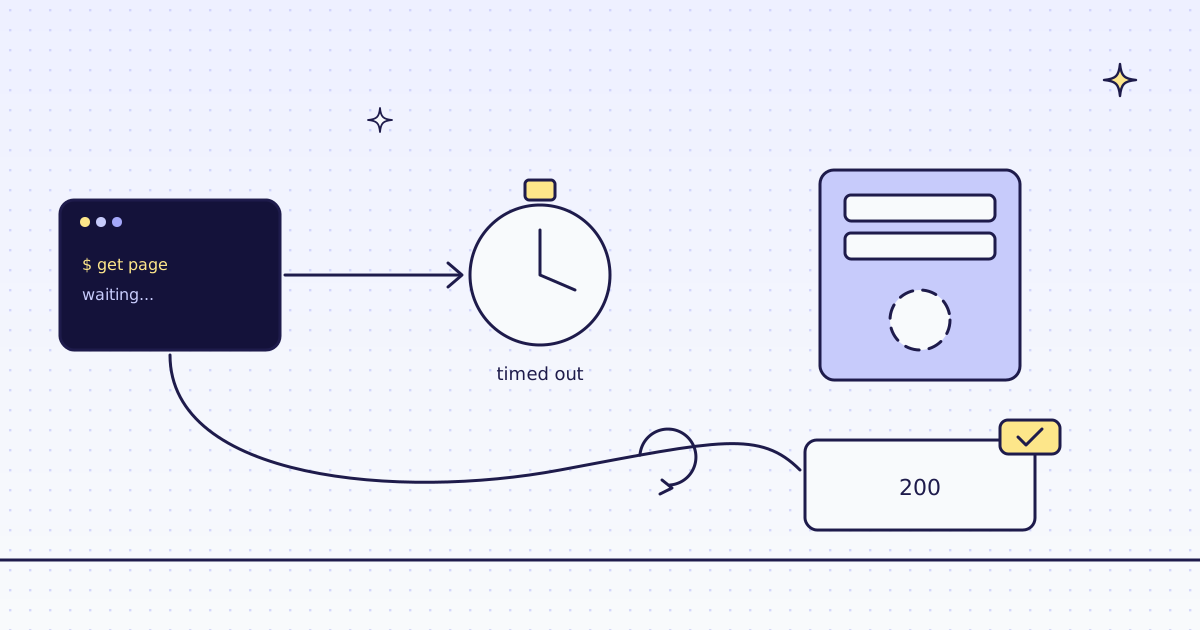
The short answer: curl has no overall time limit by default: a server that takes the connection and never answers holds it forever. Pass --max-time (-m) for the whole transfer and --connect-timeout for the connection alone. When either runs out, curl prints curl: (28) and exits with code 28, which a script can test. --retry 3 retries a timeout too, with --retry-delay between tries. For pages that need a browser or keep refusing you, send them to our API with the same curl: a call that runs out of time costs nothing.
What curl does on a slow server
Start a listener in one terminal with nc -lk 8799. It takes each connection and never answers, like a server that hangs. Run this in a second terminal:
timeout 10 curl -sS http://127.0.0.1:8799/; echo "exit code: $?"
curl -sS --max-time 5 http://127.0.0.1:8799/; echo "exit code: $?"
exit code: 124
curl: (28) Operation timed out after 5002 milliseconds with 0 bytes received
exit code: 28
- The first call had no limit and was still waiting after 10 seconds, when the shell's
timeoutstopped it with code 124. --max-time 5stopped the second one at 5 seconds, with error 28 and0 bytes received: the server took the connection and sent nothing.
How curl reports a timeout
Our test store answers fast, so give it a limit too short to meet. The error is the same one a slow site gives you:
curl -sS -o /dev/null --max-time 0.01 https://lab.megalania.io/faq/; echo "exit code: $?"
curl -sS -o /dev/null -w '%{http_code} in %{time_total} s\n' --max-time 20 https://lab.megalania.io/faq/curl: (28) Connection timed out after 36 milliseconds exit code: 28 200 in 0.058808 s
--max-time 0.01ran out while curl was still making the TLS connection, so the message saysConnection timed out, and it fired at 36 ms, not 10.- The same page with a 20-second limit took 59 ms. Same result 3 runs out of 3.
The free fix: timeouts and retries
Set a limit on every request, and retry a few times with a pause. This fixes servers that are slow now and then:
curl -sS -o /dev/null --connect-timeout 5 --max-time 2 --retry 2 --retry-delay 1 http://127.0.0.1:8799/; echo "exit code: $?"
curl -sS -o /dev/null -w '%{http_code} in %{time_total} s, %{num_retries} retries\n' \
  --connect-timeout 5 --max-time 20 --retry 3 --retry-delay 2 \
https://lab.megalania.io/faq/curl: (28) Operation timed out after 2002 milliseconds with 0 bytes received curl: (28) Operation timed out after 2009 milliseconds with 0 bytes received curl: (28) Operation timed out after 2002 milliseconds with 0 bytes received exit code: 28 200 in 0.060003 s, 0 retries
- Three error lines for one command: the first try and two retries, each stopped at 2 seconds by
--max-time, which applies to each try. -sShides curl'sWill retrywarnings but keeps the errors.%{num_retries}in-wtells you how many retries a call needed.
The fix that climbs: our API
Send the page to our API instead. We fetch it, run a real Chrome when you ask, and an answer that runs out of time costs nothing:
curl -sS --max-time 100 https://get.megalania.io/v1 \
  -H "Authorization: Bearer $MEG_API_KEY" -H 'Content-Type: application/json' \
  -d '{"url": "https://lab.megalania.io/shipping/", "response_types": "markdown"}' \
  -D - -o page.md | grep -iE '^(HTTP|x-route|x-credits-charged)'
head -c 90 page.mdHTTP/2 200 x-credits-charged: 1 x-route: http/datacenter # Shipping We pack every order by hand in recycled cardboard and paper tape. No plastic f
-D -prints our headers and-o page.mdkeeps the page:x-routesays plain HTTP was enough.--max-time 100is longer than our own limit of 90 seconds a page, so curl never cuts our answer short.
The same call on a page whose list never finishes loading, with a 20-second limit:
curl -sS --max-time 100 https://get.megalania.io/v1 \
  -H "Authorization: Bearer $MEG_API_KEY" -H 'Content-Type: application/json' \
  -d '{"url": "https://lab.megalania.io/new-arrivals/", "engine": "browser", "actions": "wait_for:#item-99", "timeout": 20}' \
-w '\n%{http_code} after %{time_total} s\n'{"error":{"code":"action_failed","field":"actions","message":"actions entry 0 could not run: no visible element matched its select
422 after 13.795795 s#item-99never appears, so our Chrome waited until the time for actions ran out. We answered422in 14 seconds, inside your 20.- Without
-f, curl exits 0 on a422. Read%{http_code}, or add--fail-with-bodyto get exit code 22 and the body.
One honest note: our test store is fast, so these runs show a short limit or a page that never gets ready, not a slow site. On a slow site, the call is the same; the price depends on the route that worked, and our MCP tool check_site tells you that price for free.
What it costs
| What we ran | Route | Credits |
|---|---|---|
| The shipping page as Markdown | h:dc | 1 |
| A page that never got ready, in the browser | c:dc | 0 |
The nc runs and the short limit, straight from curl | none | 0 |
Every rule is in Credits. Plans are on the pricing page.
How we measured: curl 8.14.1 with OpenSSL on Debian, one Linux server, 17 Nov 2026. nc -lk 8799 (OpenBSD netcat) as a server that never answers, and the shell's timeout to stop the call with no limit. Our test store for the short limit and for the second half of the fix. Our API on our dev cluster for the last two calls, against the same store on our dev domain. The outputs are copied from those runs.
Limits
- Public pages only. We do not log in, and we do not solve CAPTCHAs. When a page needs either, we stop and say so, for free.
- A page built by JavaScript needs
engine=browser. It costs more. See How to scrape JavaScript-rendered pages. - Slow can mean slow down. A site that answers slowly may be under load. Keep your rate low, fetch public pages only, and follow the site's terms and robots.txt.
What to do when a site answers 429 instead is in 429 Too Many Requests when scraping.