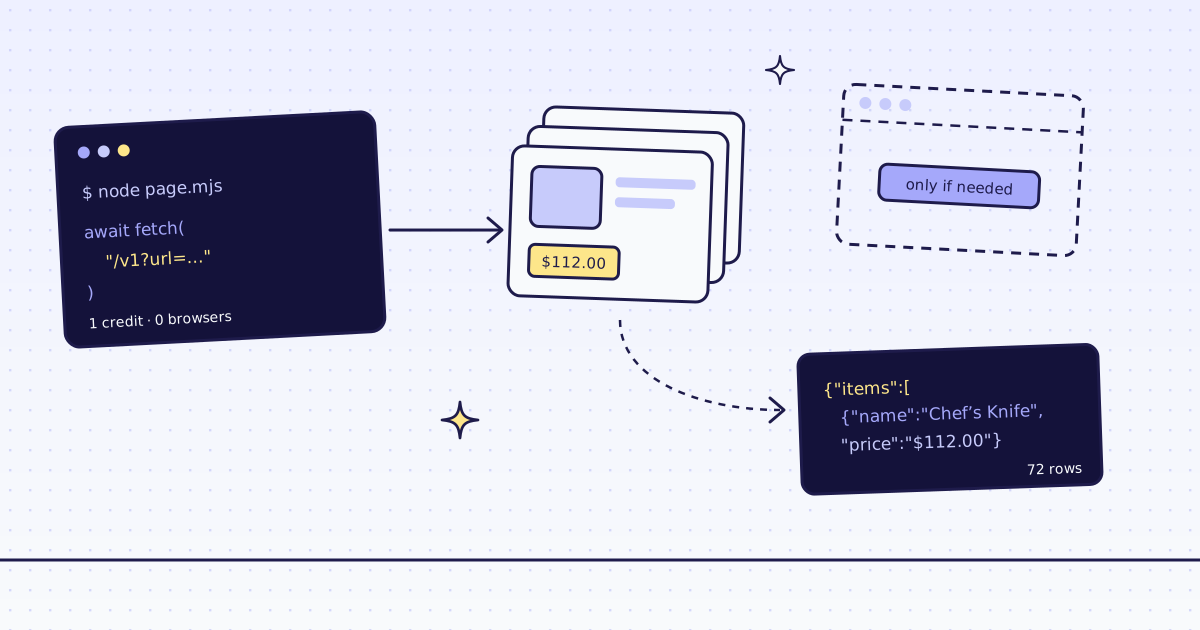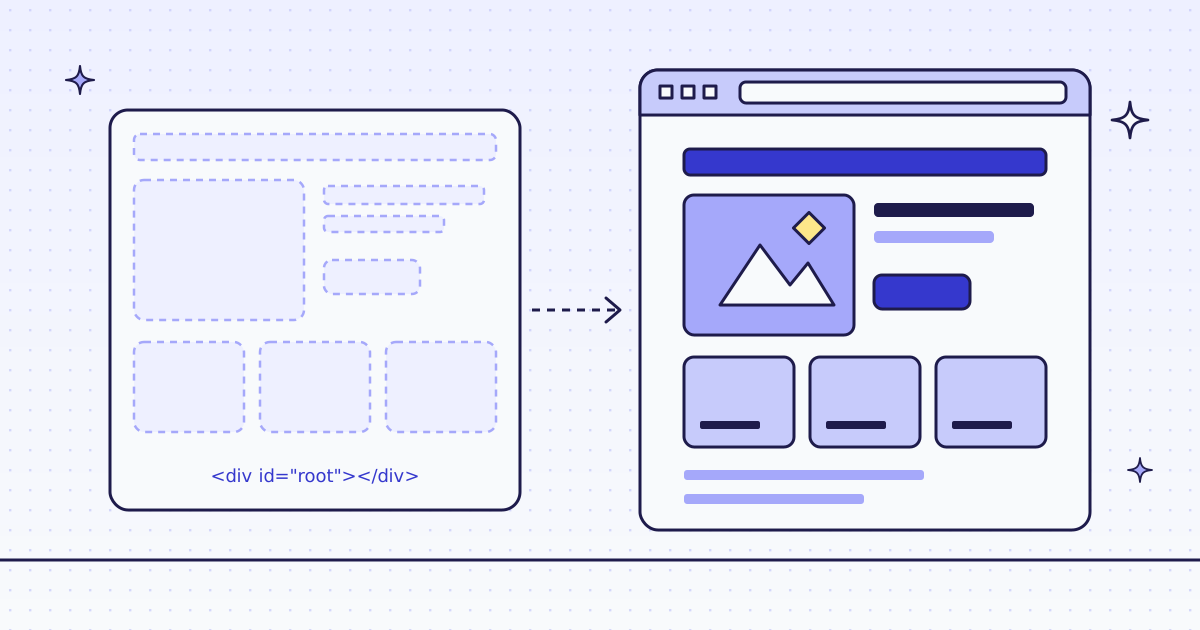
The short answer: axios downloads a page's HTML, and that is all. It does not run the page's JavaScript, so a list the page draws after it loads is not there: the <ul> is empty, the status is 200, and nothing throws. Count the items you expected and fail loudly when there are none. The free fix is often in the page itself: its script fetches the list from a JSON address you can call with axios too. When there is no such address, or it needs a token, send the page to our API with engine=browser: a real Chrome runs the script, and you get the items as JSON.
What axios gets back
Our test store's new arrivals page draws its list with JavaScript after it loads. Fetch it the plain way:
// npm install axios
import axios from "axios";

const res = await axios.get("https://lab.megalania.io/new-arrivals/");
console.log(res.status, res.statusText, "|", res.data.length, "characters of HTML");
console.log(res.data.match(/<ul id="arrivals"[^>]*>[\s\S]*?<\/ul>/)[0]);200 OK | 56548 characters of HTML <ul id="arrivals" class="products columns-4"></ul>
- 56,548 characters and a
200, but the list is empty. The page ships<ul id="arrivals">with nothing in it. In a browser, the page's script fills it with 12 products a moment later. - axios is right: that is the page the server sent. The products come later, from a second request the browser makes when it runs the script.
How axios reports an empty page
Nothing fails, so nothing tells you. Count what you expected to get:
// npm install axios
import axios from "axios";

const res = await axios.get("https://lab.megalania.io/new-arrivals/");
const list = res.data.match(/<ul id="arrivals"[^>]*>([\s\S]*?)<\/ul>/)[1];
const products = list.match(/<li/g) ?? [];
console.log("axios threw: no | status:", res.status, "| products in #arrivals:", products.length);
if (products.length === 0) throw new Error("expected products in #arrivals, got none");axios threw: no | status: 200 | products in #arrivals: 0 Error: expected products in #arrivals, got none
- Count inside the list, not the whole page. Our first try counted every product card in the HTML and found 24, from other parts of the page. Inside
#arrivalsthere were 0. - The
throwis yours. axios only throws on network errors and statuses outside 200 to 299, so an empty page passes every check it makes.
The free fix: the page's own API
The page's own script fetches the list from the store's JSON API. Call that address yourself, for free:
// npm install axios
import axios from "axios";

const page = await axios.get("https://lab.megalania.io/new-arrivals/");
const call = page.data.match(/fetch\("([^"]+)"/)[1];
console.log("the page's script calls:", call);
const api = await axios.get(new URL(call + "1", "https://lab.megalania.io/").href);
console.log(api.status, "|", api.data.length, "products |", api.data[0].name, api.data[0].prices.price);the page's script calls: /wp-json/wc/store/v1/products?orderby=title&order=asc&per_page=12&page= 200 | 12 products | 20 cm Chef’s Knife 11200
- The address was in the page's own HTML. The script calls the store's JSON API with
page=at the end; we added1. Same 12 products, as JSON, for free. - Prices are in minor units:
11200is $112.00. The’is the store's own escaping of an apostrophe; decode it before you show it.
The fix that climbs: our API
Or send the page to our API with engine=browser. A real Chrome runs the page's script, and we return the fields:
// npm install axios
// Run: MEG_API_KEY=YOUR_KEY node fetch.mjs browser
import axios from "axios";

const resp = await axios.post(
  "https://get.megalania.io/v1",
  {
    url: "https://lab.megalania.io/new-arrivals/",
    response_types: "json",
    extract: "items:#arrivals li{name:h2|price:.price}*",
    ...(process.argv[2] === "browser" && { engine: "browser", actions: "wait_for:#item-12" }),
  },
  { headers: { Authorization: `Bearer ${process.env.MEG_API_KEY}` }, timeout: 90000, validateStatus: () => true },
);
console.log("status:", resp.status, "route:", resp.headers["x-route"], "credits:", resp.headers["x-credits-charged"]);
console.log(resp.data.items.length, "products |", JSON.stringify(resp.data.items[1] ?? null));status: 200 route: browser/datacenter credits: 19
12 products | {"name":"Alpine Down Parka","price":"$349.00"}node fetch.mjs browseraddsengine: "browser"and a wait for the 12th card. Our Chrome ran the page's script, and theextractrule read the 12 cards.- 19 credits: 15 for the browser, 1 for JSON and 3 for the wait.
The same call without the browser, on the same page:
MEG_API_KEY=YOUR_KEY node fetch.mjs
status: 200 route: http/datacenter credits: 2
0 products | null
- Without
browser, we fetched over plain HTTP and saw the same empty list. A200, 0 products, and 2 credits charged: 1 for the page and 1 for JSON. - When our check sees a page that is only a JavaScript shell, we say so in
X-Hint: needs_jsand charge nothing. This page has a heading and some text, so the check did not fire. Count your rows on our answers too.
One honest note: our check for JavaScript shells did not flag this page, because it has a heading and some text. So the plain call was charged for an empty list. Count your rows on every answer, ours included.
What it costs
| What we ran | Route | Credits |
|---|---|---|
| The page in our browser, 12 products as JSON | c:dc | 19 |
| The same page over plain HTTP: an empty list | h:dc | 2 |
gets.mjs, seen.mjs and fix.mjs, straight from Node | none | 0 |
Every rule is in Credits. Plans are on the pricing page.
How we measured: axios 1.21.1 on Node 24.21, one Linux server, 16 Nov 2026. Our test store's new arrivals page, which draws 12 products with JavaScript, for the first three scripts. Our API on our dev cluster for fetch.mjs, against the same store on our dev domain. The outputs are copied from those runs.
Limits
- Public pages only. We do not log in, and we do not solve CAPTCHAs. When a page needs either, we stop and say so, for free.
- A page built by JavaScript needs
engine=browser. It costs more. See How to scrape JavaScript-rendered pages. - Read the site's terms. A page's JSON API is public when the page calls it with no key, but follow the site's terms and robots.txt.
More ways to tell which pages need a browser are in How to scrape JavaScript-rendered pages.