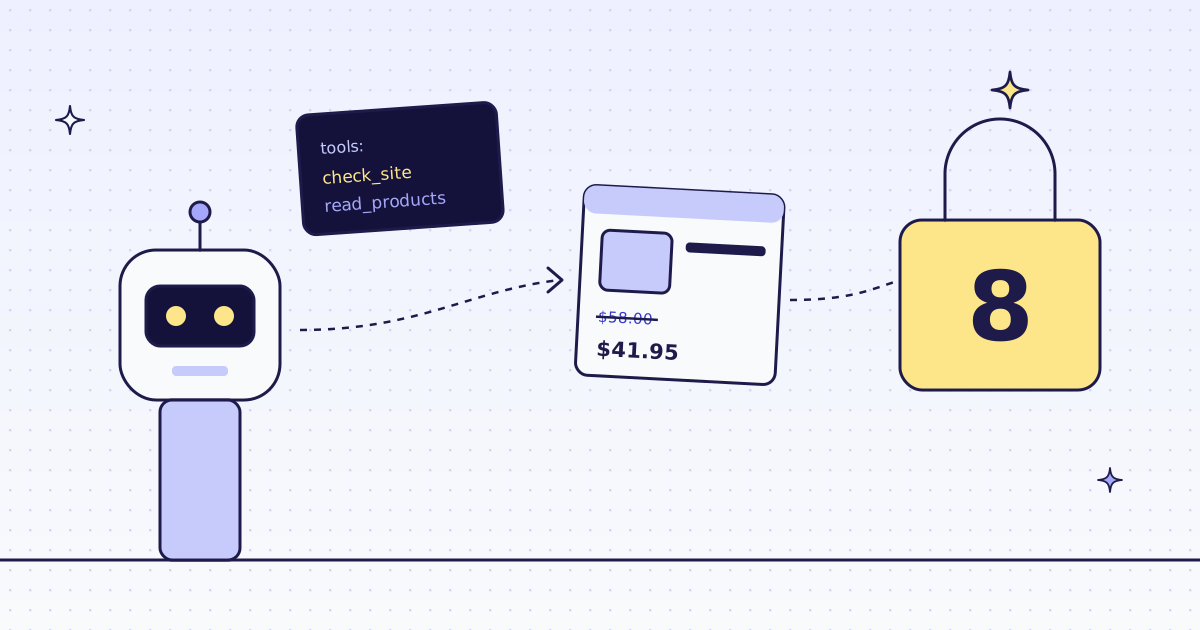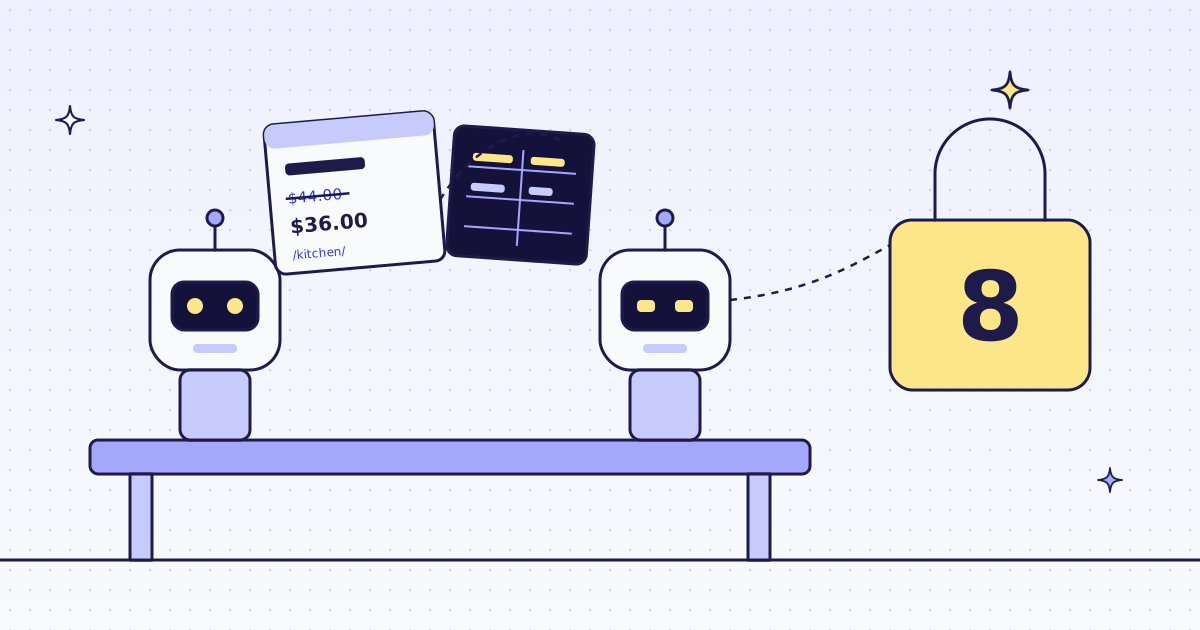
The short answer: for CrewAI web scraping, give the agent our MCP server in mcps=, with your key in the Authorization header and a filter that keeps two tools: check_site and extract. CrewAI turns them into tools the agent can call. To lock the cost, wrap extract in a small @tool with a fixed max_credits, so the model cannot raise it. On our test store, lab.megalania.io, the check was free, and each list page came back as JSON for 2 credits.
What is packaged, and what is not
We have no CrewAI package. You do not need one: CrewAI speaks MCP, and our MCP server is the product. This post uses CrewAI’s own MCP support, MCPServerHTTP from crewai.mcp, and our server at https://mcp.megalania.io. We do ship packages for LangChain, LlamaIndex and the Vercel AI SDK.
Install CrewAI and set your key:
pip install crewai
export MEG_API_KEY='meg_sk_...'
Connect the server: one config
import json
import os

from crewai import Agent
from crewai.mcp import MCPServerHTTP, create_static_tool_filter

megalania = MCPServerHTTP(
    url="https://mcp.megalania.io",
    headers={"Authorization": f"Bearer {os.environ['MEG_API_KEY']}"},
    tool_filter=create_static_tool_filter(allowed_tool_names=["check_site", "extract"]),
)
reader = Agent(role="Page reader", goal="Read store pages", backstory="You read web pages.", mcps=[megalania])
tools = {t.name.removeprefix("mcp_megalania_io_"): t for t in reader.get_mcp_tools([megalania])}
print("tools:", sorted(tools))- The key goes in a header, never in the URL. A key in a URL ends up in logs and in shell history.
- The filter keeps two of our fifteen tools. Fewer tools means a shorter prompt for the model and fewer ways to spend. The full list is in MCP for agents.
- CrewAI adds a prefix to each name, from the server’s host:
extractbecomesmcp_megalania_io_extract. The last line strips it, so the code below can saytools["extract"].
Call the tools yourself first
A crew needs a model, and a model needs your own model key. The tools do not. Call them straight from Python first, so you know what the agent will get back. Add this to crew_tools.py:
site = json.loads(tools["check_site"].run(host="lab.megalania.io"))
print("price per page:", site["price"]["quotes"])

CARDS = "items:li.product{name:h2|was:.price del .amount|now:.price ins .amount|price:.price .amount}*"
pages = {}
for path in ["/deals/", "/product-category/kitchen/"]:
    text = tools["extract"].run(url=f"https://lab.megalania.io{path}", extract=CARDS, max_credits=8)
    body, _, cost = text.rpartition("credits_charged:")
    pages[path] = json.loads(body)["items"]
    print(path, len(pages[path]), "products,", cost.strip(), "credits")

deals = {p["name"] for p in pages["/deals/"]}
for p in pages["/product-category/kitchen/"]:
    if p["now"]:
        print("on sale:", p["name"], p["was"], "->", p["now"], "| on /deals/:", p["name"] in deals)
What it printed:
tools: ['check_site', 'extract']
price per page: {'browser': 15, 'browser_residential': 32, 'datacenter': 1, 'residential': 8}
/deals/ 8 products, 2 credits
/product-category/kitchen/ 9 products, 2 credits
on sale: Porcelain Teapot with Oak Handle $44.00 -> $36.00 | on /deals/: Falsecheck_siteis free. It says a plain page costs 1 credit on this site and a browser page 15, before you spend anything.extractreads fields with CSS rules.items:li.product{...}*gives one object per product card. A field a card does not have, likenowon a product that is not on sale, isnull, so rows never shift. The rules are in Fetch.- Each page cost 2 credits: 1 for the page on the datacenter route, 1 for the JSON output. The tool’s text ends with a
credits_charged:line, which the code reads. - A run again within 5 minutes cost 1 credit a page. The pages came from our cache.
And the answer to a real question: one kitchen product is on sale, 18% off, and the deals page does not list it. That is the job for the crew.
Lock the cost: a tool with a fixed max_credits
max_credits is the most one page may cost. On our MCP server it is an argument of extract, and the model fills it. A model can leave it out, or write 100. So do not hand extract to the agent. Hand it a tool of your own, where you choose the rules, the cap and the site:
from crewai import Crew, Task
from crewai.tools import tool


@tool("read_products")
def read_products(url: str) -> str:
    """Read the product cards on one lab.megalania.io list page as JSON: name, was (old price), now (sale price), price."""
    if not url.startswith("https://lab.megalania.io/"):
        return "refused: this tool reads lab.megalania.io only"
    return tools["extract"].run(url=url, extract=CARDS, max_credits=8)
The model sees one argument, url. It cannot change the cap of 8, and it cannot send the tool to another site. We called the tool with another host: it answered “refused” and sent no request. With the Lab’s deals page, it returned the 8 products. A page whose cheapest route costs more than 8 is refused before any try, for free.
The crew: a reader and an analyst
Two agents. The reader has only read_products. The analyst has no tools at all: it works on what the reader found.
shopper = Agent(
    role="Store reader",
    goal="Read product lists exactly as the pages show them",
    backstory="You copy prices from pages. You never guess a price.",
    tools=[read_products],
    max_iter=4,
)
analyst = Agent(
    role="Deal analyst",
    goal="Find sale items that the deals page misses",
    backstory="You compare two lists and report only what the data shows.",
    max_iter=2,
)
read = Task(
    description="Read https://lab.megalania.io/deals/ and https://lab.megalania.io/product-category/kitchen/ with read_products.",
    expected_output="Both product lists as JSON",
    agent=shopper,
)
compare = Task(
    description="List the kitchen products that have a sale price. For each, give the discount in percent and say if it is on the deals page.",
    expected_output="A short Markdown table",
    agent=analyst,
    context=[read],
)
crew = Crew(agents=[shopper, analyst], tasks=[read, compare])
print(crew.kickoff())max_iteris the most steps an agent may take. With 4, a stuck reader stops after 4 steps, and no page in any step costs more than 8.context=[read]gives the analyst the reader’s output. It never touches a page.- The model is yours. CrewAI uses the model you set on each agent with
llm=, and your own key for it.
We built this crew and called read_products on our dev cluster. We did not run kickoff(): it calls a model, and we do not put a model key in our test runs. So we show no answer from the crew here. The tool output above is what the reader gets.
For a run budget across many calls, not one page, see Cap what an AI agent spends on web pages. The same counter fits inside read_products.
What it costs
| Call | Credits |
|---|---|
check_site |
0 |
extract on one Lab list page, datacenter route |
2 |
| The same call again within 5 minutes (cache hit) | 1 |
A page over max_credits (refused before any try) |
0 |
| A block we detect, and every error of ours | 0 |
These prices are for the Lab. A site that blocks the datacenter route costs more; check_site tells you how much, for free. All the rules are in Credits. Plans are on the pricing page.
For the same prices from Claude, Cursor or ChatGPT with no code, see Scrape product prices with an AI agent. For the setup in other clients, see Give your AI agent web access with an MCP server.
How we measured: our dev cluster on 16 Nov 2026, the Lab store on our dev domain, Python 3.13, CrewAI 1.15.41. crew_tools.py ran three times: the first run is the output above; the repeats within 5 minutes cost 1 credit a page. read_products was called twice with the Lab and twice with another host.
Limits
- We did not run a crew with a model. What a model does with these tools depends on the model and your prompt.
- Use
mcps=on the agent. We also triedMCPServerAdapterfromcrewai-tools1.15.41. It sends every empty argument asnull, and ourextractrefused the call for an emptyactionsargument, for free.check_site, with one argument, worked. - The rules are per site.
li.productis WooCommerce. On another store, ourinspecttool suggests rules that it checked on the page. - We read pages, we do not search. The crew needs the URLs, from you or from a search tool of its own.
Fetch public pages only. Read the site’s terms and robots.txt, and follow them.