The short answer: an infinite-scroll page gets its next items from a JSON URL each time you reach the bottom. Call that URL yourself, page by page: it is free and fast. If you cannot, for example because the URL needs tokens the page makes on the fly, send the page to us with actions: we open it in a real Chrome, scroll to the bottom as many times as you ask, and return the full page. Add "network": "true" to also get the JSON the page loaded while it scrolled. Actions add 3 credits to a browser page, which starts at 15.
How infinite scroll works
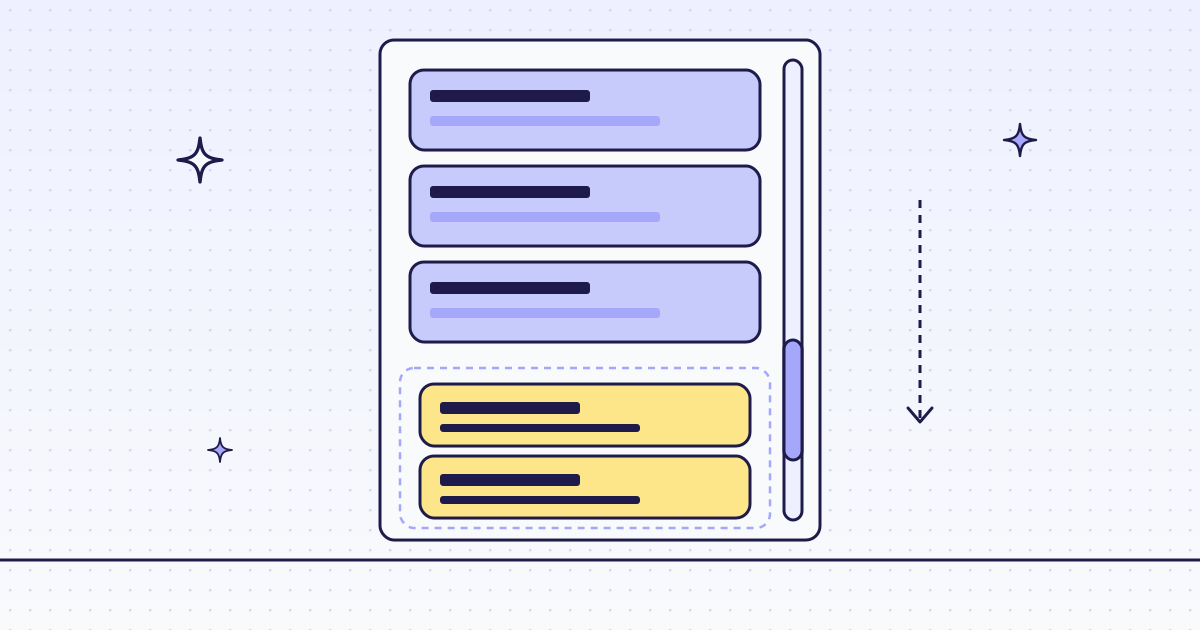
The first HTML has 10 or 20 items. A script watches the scroll position. Near the bottom it calls a URL like /api/items?page=2, gets JSON, and adds the items to the page. A “Load more” button does the same on a click. So the data you want arrives as JSON, one page at a time, and the HTML you fetched first never has more than the first page.
The free way: call the JSON yourself
Open the page in your browser, then developer tools, Network tab, filter on “Fetch/XHR”, and scroll. Each new batch of items shows up as a request. Click it and look at the URL and the answer. On our practice page it looks like this:
curl -s "https://quotes.toscrape.com/api/quotes?page=2" | head -c 300
Change the page number and loop until the answer says there is no next page. This is the best way when it works: no browser, no HTML, clean JSON.
It stops working when the URL needs a token or a signature the page makes in JavaScript, when the API refuses requests that do not come from the page, or when the site blocks your server’s IP.
Check a site first
Before a big run, ask about the host. It is free. Over MCP, your agent calls check_site:
{"name": "check_site", "arguments": {"host": "quotes.toscrape.com"}}From cURL, the same answer is two calls: /v1/tier for the price, /v1/stats/domain for how our routes have done there lately.
curl -s -H "Authorization: Bearer YOUR_KEY" \
  "https://get.megalania.io/v1/tier?host=quotes.toscrape.com"
curl -s -H "Authorization: Bearer YOUR_KEY" \
  "https://get.megalania.io/v1/stats/domain?host=quotes.toscrape.com&days=30"
capabilities.browser must list a tier: actions need the browser. Check a site first explains every field.
Scroll in a real browser (cURL)
actions is a list of steps joined by |. This one scrolls to the bottom three times and waits 1.5 seconds after each, so the page can load the next items:
curl -sS https://get.megalania.io/v1 \
  -H "Authorization: Bearer YOUR_KEY" \
  -H "Content-Type: application/json" \
  -D headers.txt -o page.md \
  -d '{"url": "https://quotes.toscrape.com/scroll", "actions": "scroll:bottom|wait:1500|scroll:bottom|wait:1500|scroll:bottom|wait:1500", "response_types": "markdown", "max_credits": "128"}'
page.md now holds the items of four loads, not one. actions needs the browser, so you do not have to send engine. A browser page costs more than HTTP, so we gave max_credits room.
For a “Load more” button, click it and wait for an item that only exists after the click:
click:button.load-more|wait_for:.item:nth-of-type(21)|click:button.load-more|wait:1500
The steps you can send
At most 20 entries, and 30 seconds for all of them together:
| Entry | What it does |
|---|---|
scroll:bottom |
scrolls to the bottom; scroll:top and scroll:800 (pixels) work too |
wait:1500 |
waits 1 to 10,000 ms |
wait_for:.item |
waits up to 10 s for a visible element that matches |
click:.more |
clicks the first visible match |
type:#q=shoes |
types text into the first visible match |
press:Enter |
presses one key |
If a step cannot run, for example no visible match in time, the answer is a free 422 action_failed, and the message names the step’s index.
Python: the items and the JSON behind them
"network": "true" returns, next to the page, each JSON answer the page loaded while it scrolled. network_url_globs keeps only the ones you want. The answer is then multipart/mixed: one part for the page, one for the network log.
# pip install requests
# Run: MEG_API_KEY=YOUR_KEY python scroll_and_capture.py https://quotes.toscrape.com/scroll
import json
import os
import sys
import uuid
from email.parser import BytesParser
from email.policy import default

import requests

resp = requests.post(
    "https://get.megalania.io/v1",
    headers={
        "Authorization": f"Bearer {os.environ['MEG_API_KEY']}",
        "Idempotency-Key": str(uuid.uuid4()),
    },
    json={
        "url": sys.argv[1],
        "actions": "scroll:bottom|wait:1500|scroll:bottom|wait:1500|scroll:bottom|wait:1500",
        "response_types": "markdown",
        "network": "true",
        "network_url_globs": "*/api/*",
        "max_credits": "128",
    },
    timeout=120,
)
if resp.status_code != 200:
    err = resp.json()["error"]
    sys.exit(f"{resp.status_code} {err['code']}: {err['message']}")

msg = BytesParser(policy=default).parsebytes(b"Content-Type: " + resp.headers["Content-Type"].encode() + b"\r\n\r\n" + resp.content)
for part in msg.iter_parts():
    name = part.get_param("name", header="content-disposition")
    if name == "markdown":
        with open("page.md", "w", encoding="utf-8") as f:
            f.write(part.get_content())
    if name == "network":
        for line in part.get_content().splitlines():
            r = json.loads(line)
            print(r["status"], r["url"], r["bytes"], "bytes")
print("credits:", resp.headers["X-Credits-Charged"])
Each network line is one response: url, method, status, content_type, bytes, truncated and body. Once you see the JSON URL there, try the free way above with it.
Try it on our Lab. lab.megalania.io/scroll is our own test page: ten items come with the page, and each scroll to the bottom adds ten more. Send actions=scroll:bottom|wait_for:#item-20 and you get twenty.
What it costs
A page with actions is a browser page, plus 3 credits however many steps run. Network capture adds 0.
| Route | Credits a page | Included data | With actions |
|---|---|---|---|
Browser, datacenter (c:dc) |
15 | 1 MiB | 18 |
Browser, residential (c:res) |
32 | 64 KiB | 35 |
Each started 128 KiB above the included data adds 1 on c:dc and 8 on c:res. A page that scrolled four times is bigger than one that did not, so the size counts more on c:res. Run check_site (free) to see the price for your site. A block we detect is free, and so is a step that cannot run.
Limits
- 30 seconds for all actions, inside
timeout(at most 90). - Many pages: a batch takes
actionsandnetworktoo, with the same prices and the same failure cap. - Iframes and shadow roots: selectors do not reach into them.
- Endless feeds: pick a number of scrolls. A feed that never ends never finishes.
- Terms: this is not legal advice. Read each site’s terms and robots.txt, and follow them.
Every action and every network field: Page actions and Network capture.